

TL;DR:
- Website uptime monitoring verifies that websites stay accessible and functioning, reducing revenue loss from undetected outages. Implementing layered tests including content validation and multi-region checks ensures accurate detection of real issues. Regular review and smart alert policies prevent false positives and alert fatigue, maintaining a reliable monitoring process.
Website uptime monitoring is the continuous, external verification that your site is accessible and functioning correctly, and it is the first line of defence against revenue loss caused by undetected downtime. The industry standard for high-availability sites is 99.9% uptime, which still permits roughly 8 hours and 45 minutes of downtime per year. For agencies managing WordPress sites on behalf of clients, that number is not a comfort. It is a liability. Tools like UptimeRobot, Uptrends, and Uptime.com have made the website uptime monitoring process accessible to teams of any size, but having a tool is not the same as having a process. This guide covers both.
What does the website uptime monitoring process actually involve?
Uptime monitoring is not a single check. It is a layered system of automated tests that together confirm your site is reachable, functioning, and serving real content to real users.
The core check types every monitoring setup should include are:
- HTTP status checks — confirm the server returns a 200 OK response
- Content validation — verify that a specific keyword or element appears on the page, catching zombie sites that respond with a success code but deliver broken content
- SSL certificate monitoring — track expiry dates and alert at 30, 14, and 7 days before expiration
- DNS resolution checks — confirm the domain resolves correctly
- TCP port checks — verify that specific ports (such as 443 or 3306) are open and responding
Content validation is the check most teams skip. A site can return a 200 OK status while displaying a fatal PHP error or a blank white screen. Basic HTTP monitoring misses this entirely. Content keyword validation closes that blind spot.
Pro Tip: Never rely solely on internal monitoring tools. Internal systems share infrastructure with the site itself, which means a full server outage takes down both the site and the monitor at the same time. External monitoring is the only way to detect a complete system failure reliably.
Comparing popular uptime tracking tools
| Tool | Check interval | Multi-region | Content validation | SSL monitoring |
|---|---|---|---|---|
| UptimeRobot | 1 minute (free) | Limited on free plan | Yes | Yes |
| Uptrends | 1 minute | Yes (200+ locations) | Yes | Yes |
| Uptime.com | 1 minute | Yes | Yes | Yes |
| Better Uptime | 30 seconds | Yes | Yes | Yes |
The right tool depends on your client portfolio size and the check frequency you need. For production WordPress sites, a 30-second interval is the target.
How to set up a website uptime monitoring process step by step
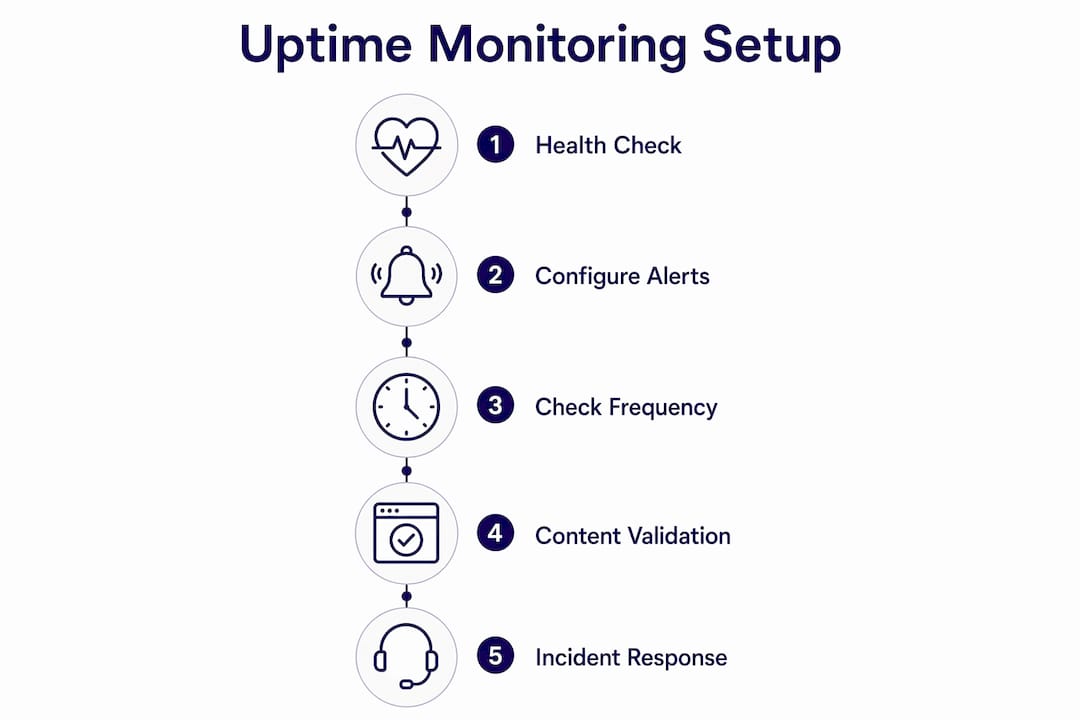
A working monitoring setup takes less than an hour to configure correctly. Most teams spend that hour on the wrong things. Follow this sequence instead.
-
Choose an external monitoring tool. UptimeRobot works for basic setups. Uptrends or Uptime.com suit agencies managing multiple client sites with SLA commitments.
-
Configure checks from at least three geographic locations. Multi-region monitoring from a minimum of three geographically diverse locations distinguishes true downtime from a localised network fault. A site appearing down from London but live from Frankfurt and New York is a routing issue, not a full outage.
-
Set check intervals aligned to site priority. Production sites need 30 to 60-second intervals. General business sites can use 1 to 5-minute intervals without meaningful risk. Matching the interval to the site’s commercial importance keeps alert noise manageable.
-
Add content validation to every critical page. Choose a keyword that appears only when the page loads correctly, such as a product name or a heading unique to that page. If the keyword is absent, the check fails regardless of the HTTP status code.
-
Configure SSL certificate alerts at 30, 14, and 7 days before expiry. SSL auto-renewal tools like Let’s Encrypt fail silently more often than most teams expect. Proactive SSL monitoring catches the failure before visitors see a browser security warning.
-
Define alert thresholds using multi-check confirmation. Require failures from at least two distinct geographic locations before triggering an alert. Single-location failures are almost always false positives caused by a temporary network issue.
-
Set up escalation policies. The first alert goes to the on-call person. If unacknowledged within ten minutes, it escalates to a second contact. Tools like PagerDuty and Opsgenie handle this natively. Uptime.com and Better Uptime have built-in escalation features.
-
Create a public status page. A status page at status.yourclientdomain.com gives clients and their users a transparent view of incidents. It reduces inbound support calls during outages and builds trust.
Pro Tip: Run a website health check across your full client portfolio before configuring alerts. Sites with existing errors will generate false alerts from day one, and you will spend the first week chasing problems that predate your monitoring setup.
If you manage WordPress sites for multiple clients and want to see how much revenue is sitting uncaptured in your existing portfolio, the Wpcto WordPress Profit Calculator shows you the number in under 90 seconds.
What common challenges arise during uptime monitoring?
Even a well-configured monitoring setup produces problems. Knowing what to expect prevents those problems from undermining the entire system.
False positives are the most common issue. A single monitoring location reporting a failure when all others show the site as live is almost always a network routing problem, not a site outage. Multi-check confirmation requiring failures from two or more distinct locations before triggering an alert eliminates the majority of false positives.
Alert fatigue is the second major risk. When a monitoring team receives too many alerts, they start ignoring them. Alert fatigue is the leading cause of monitoring teams missing real incidents. Smart escalation policies, confirmation checks, and sensible thresholds keep alert volume low enough that every notification carries weight.
Zombie sites are a subtler problem. A WordPress site can serve a 200 OK response while displaying a broken page caused by a failed plugin update or a database connection error. Content keyword validation is the only check that catches this. Without it, your monitoring dashboard shows green while your client’s customers see an error page.
SSL certificate failures catch teams off guard even when auto-renewal is in place. Let’s Encrypt renewals fail for reasons including DNS misconfiguration, server permission errors, and rate limiting. Configuring alerts at 30, 14, and 7 days before expiry gives enough time to investigate and fix the issue before visitors are affected.
“Effective uptime monitoring includes incident response processes featuring clear escalation paths, real-time status page updates, and post-incident reviews.” — Website uptime monitoring best practices
Every team managing production sites needs a written incident response runbook. It does not need to be long. It needs to answer three questions: who gets alerted, what do they check first, and who has the authority to take the site offline for emergency maintenance.
How does uptime monitoring connect to broader website maintenance goals?
Uptime monitoring does not exist in isolation. It is one component of a wider website maintenance practice that together protects site reliability, client trust, and search engine performance.
The connections worth understanding are:
- Service level agreements. If you offer clients a guaranteed uptime figure, your monitoring data is the evidence that backs it up. A WordPress SLA without monitoring data behind it is an unenforceable promise.
- SEO impact. Google’s crawlers encounter downtime the same way users do. Repeated downtime signals during crawl windows can suppress rankings. Monitoring gives you the data to identify and address recurring outage windows before they affect search visibility.
- Revenue protection. An e-commerce site down for one hour during peak trading loses real money. Monitoring with short check intervals and fast alerting minimises the window between failure and recovery.
- Client communication. A public status page, updated in real time during an incident, reduces panicked client calls and demonstrates professionalism. Clients who can see the status themselves are easier to manage than clients who cannot.
- Multi-channel alert delivery. Routing alerts through email, SMS, Slack, and phone calls simultaneously means the right person receives the notification regardless of what they are doing. Most production monitoring tools support all four channels natively.
Uptime monitoring data also feeds directly into post-incident reviews. Knowing exactly when a site went down, which check triggered first, and how long recovery took turns every incident into a learning opportunity rather than just a crisis.
Key takeaways
A reliable website uptime monitoring process requires external, multi-region checks combined with content validation, smart alerting, and a clear incident response plan.
| Point | Details |
|---|---|
| External monitoring is non-negotiable | Internal tools share infrastructure with the site and cannot detect full outages. |
| Multi-region checks prevent false positives | Require failures from at least three locations before treating an alert as a real incident. |
| Content validation catches zombie sites | HTTP status checks alone miss broken pages that still return a 200 OK response. |
| SSL alerts need three trigger points | Set alerts at 30, 14, and 7 days before certificate expiry to catch silent renewal failures. |
| Smart alerting prevents alert fatigue | Escalation policies and confirmation checks keep alert volume low and team response sharp. |
Why most monitoring setups fail within the first month
The mistake I see most often is treating uptime monitoring as a one-time configuration task. A team sets up UptimeRobot, points it at the homepage, and considers the job done. Three months later, a client’s checkout page has been broken for two weeks and nobody noticed because the homepage was fine.
The monitoring setups that actually work are the ones that get reviewed. Check intervals get tightened as sites grow. Content validation keywords get updated when pages are redesigned. SSL alerts get verified after every certificate renewal. Alert escalation paths get updated when team members leave.
The second mistake is underestimating alert fatigue. I have worked with agencies where the monitoring inbox received 40 alerts a day. Nobody read them. When a real outage happened, it sat unacknowledged for 90 minutes because the alert looked identical to the 39 false positives that preceded it. Multi-check confirmation and sensible thresholds are not optional refinements. They are the difference between a monitoring system and a noise machine.
My honest recommendation for agencies managing WordPress sites for clients is to combine external monitoring tools with a proactive maintenance partner. Monitoring tells you when something is wrong. Maintenance reduces how often something goes wrong in the first place. The two together are what reducing WordPress downtime actually looks like in practice.
— Marcel
How Wpcto handles uptime monitoring for agencies
Wpcto manages WordPress maintenance and support for design, brand, and digital agencies across the UK. That includes uptime monitoring, security updates, plugin management, and emergency support, all handled behind the scenes so your team stays focused on client work rather than WordPress firefighting. Agencies working with Wpcto keep the client relationship and the recurring revenue without absorbing the support burden. If you want professional uptime monitoring and full WordPress care for your client sites, explore Wpcto’s agency services or check the white-label support options built specifically for growing agencies. Before you do, run the WordPress Profit Calculator to see exactly what your current client base is worth.
FAQ
What is website uptime?
Website uptime is the percentage of time a site is accessible and functioning correctly. The industry standard target is 99.9%, which allows approximately 8 hours and 45 minutes of downtime per year.
How often should uptime checks run?
Production sites need checks every 30–60 seconds. General business sites can use 1–5 minute intervals without significant risk to detection speed.
Why is external monitoring better than internal monitoring?
External monitoring tools operate independently of your server infrastructure. Internal tools share the same infrastructure as the site, so a full server failure takes both down simultaneously.
What is a zombie site in uptime monitoring?
A zombie site returns a 200 OK HTTP status but serves broken or error-filled content to visitors. Content keyword validation catches this; a basic HTTP status check does not.
How do I stop alert fatigue in my monitoring setup?
Require failures from at least two geographic locations before triggering an alert, and set escalation policies that notify a second contact only if the first does not respond within ten minutes. This keeps alert volume low and team response reliable.