

TL;DR:
- Website uptime monitoring checks site availability regularly to prevent outages. It uses layered checks from multiple locations, with alerts triggered only after confirmed failures to avoid false positives. Regular reviews and proper configurations ensure reliable monitoring and protect client trust.
Website uptime monitoring is the automated process of regularly checking your site’s availability and responsiveness to detect outages before your clients do. Tools like UptimeRobot and Pingdom run these checks continuously, measuring whether pages load, respond correctly, and serve the right content. The industry standard target is 99.9% availability, and falling short of that has real consequences for revenue, search rankings, and client trust. This website uptime monitoring guide covers everything from check intervals and multi-location verification to alert configuration and common pitfalls.
What is website uptime and why do downtime figures matter?
Website uptime is the percentage of time a site is accessible and functioning correctly for visitors. The gap between uptime percentages looks small on paper but translates into very different operational realities.
| Uptime level | Annual downtime allowed | Weekly downtime allowed |
|---|---|---|
| 99.9% | 8.76 hours | ~10 minutes |
| 99.99% | 52.56 minutes | ~1 minute |
| 99.999% | 5.26 minutes | ~6 seconds |
The difference between tiers is not academic. A site at 99.9% uptime can be offline for nearly nine hours a year without technically breaching its SLA. For an e-commerce client processing orders around the clock, that figure represents lost transactions, abandoned carts, and damaged reputation.
Downtime also affects SEO. Google’s crawlers record failed requests, and repeated crawl errors signal instability. A site that goes down during a high-traffic period, such as a product launch or a seasonal campaign, can lose rankings that take months to recover. User trust follows the same pattern. Visitors who encounter an error page rarely return immediately, and many do not return at all.
For agencies managing multiple WordPress sites, the importance of uptime monitoring is compounded. One client’s outage becomes your emergency, regardless of whether you have a support agreement in place.
How often should uptime checks run?
Check frequency is the single most consequential setting in any monitoring setup. Standard check intervals run between 1 and 5 minutes, with mission-critical pages monitored every 60 seconds and lower-priority marketing pages checked every 5 minutes.
The logic is straightforward. A checkout page going down for four minutes during peak trading costs money. A blog post going down for the same period costs almost nothing. Matching check frequency to page criticality keeps your monitoring data meaningful and your costs proportionate.
- Checkout and payment pages: every 60 seconds. Any failure here has direct revenue impact.
- Login and account pages: every 60 seconds. Authentication failures block users from accessing services.
- Homepage and key landing pages: every 1–2 minutes. These pages drive first impressions and paid traffic conversions.
- Product and service pages: every 2–3 minutes. Downtime here affects sales funnels and organic search performance.
- Blog posts and static content pages: every 5 minutes. Lower traffic and lower commercial impact justify a relaxed interval.
The trade-off is real. Higher frequency checks generate more data, consume more monitoring credits on paid plans, and increase the volume of alerts your team must process. Setting every page to 60-second checks is not the answer. Segment your site by business criticality and assign intervals accordingly.
Pro Tip: Create a simple spreadsheet listing each monitored URL, its business function, and its assigned check interval. Review it quarterly. Pages change in importance as your client’s business evolves, and your monitoring setup should reflect that.
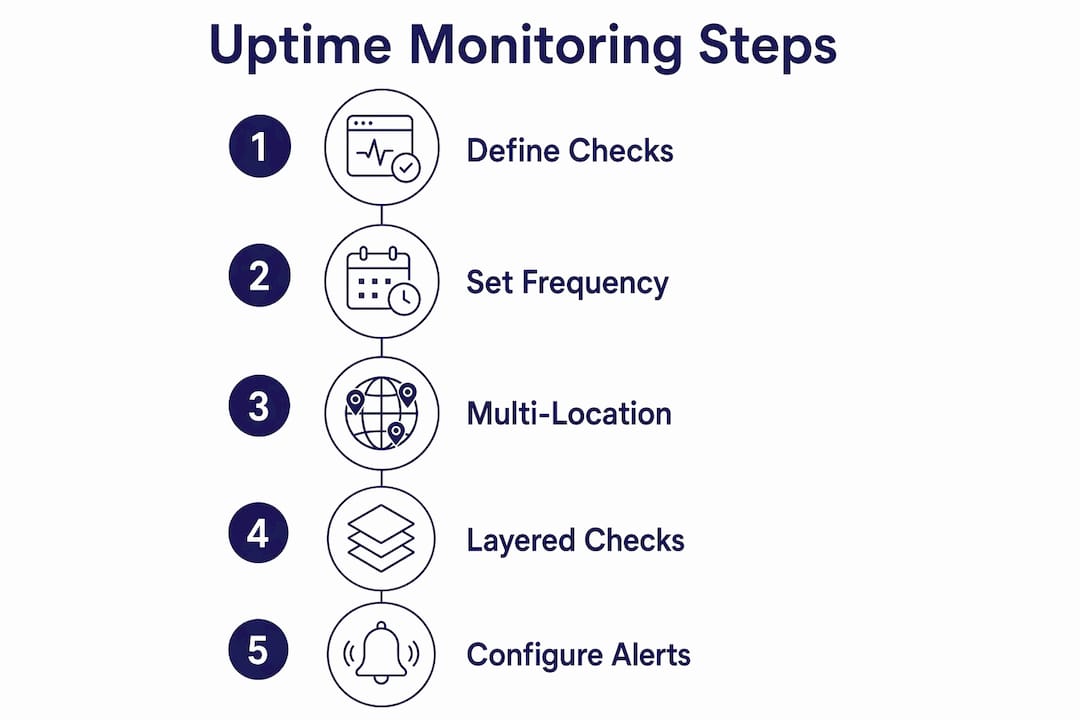
How to implement multi-location and layered monitoring
Single-location monitoring is the most common setup and the most misleading. A check from one server in London might report a site as down when the issue is a routing problem between that server and your host. The site is perfectly accessible from Manchester, Dublin, or Frankfurt.
Multi-region monitoring solves this by running checks from 3–10 geographically distinct locations simultaneously. A genuine outage fails across all regions. A local routing issue fails in one region only. The distinction matters enormously for alert accuracy and incident response.
Beyond basic availability, mature monitoring adds layers that catch issues a simple HTTP check misses entirely.
| Monitoring layer | What it checks | Why it matters |
|---|---|---|
| HTTP status code | Server response (200, 404, 500) | Confirms the server is responding |
| Keyword content check | Presence of specific page text | Confirms the right content is served |
| SSL certificate validity | Certificate expiry and chain | Prevents browser security warnings |
| DNS resolution | Domain resolves to correct IP | Catches DNS hijacking or misconfiguration |
| Response time | Time to first byte and full load | A 12-second response is technically “up” but functionally broken |
The keyword check deserves particular attention. A server can return a 200 OK status code while serving a cached error page, a maintenance notice, or a completely blank page. Keyword monitoring confirms that a specific string of text, such as your client’s company name or a product heading, is present in the response. Without it, you are checking that the server answered, not that the site is working.
Pro Tip: Use synthetic transaction monitoring for critical user paths. Tools like Pingdom and UptimeRobot support multi-step checks that simulate a login, a form submission, or an add-to-cart action. Multi-step synthetic monitoring catches functional failures that availability checks never surface.
For agencies, layered monitoring also feeds into website health reporting for clients. SSL expiry warnings, DNS anomalies, and slow response times are all reportable events that demonstrate the value of your ongoing care plan.
How should you configure alerts to avoid false positives?
Alert fatigue is the point at which your team stops taking alerts seriously because too many of them turn out to be nothing. It is a genuine operational risk, and it is entirely avoidable with the right configuration.
The foundation is a timeout threshold of 10 seconds with a minimum of two retries before any alert fires. A single failed check is not an outage. Network packets drop, servers hiccup, and monitoring nodes have momentary issues. Retesting and waiting for multiple consecutive failures before alerting reduces noise and leads to more efficient incident response.
The gold standard is two consecutive failures from two distinct geographic regions before triggering an urgent alert. This combination eliminates transient network issues and single-location anomalies in one rule.
Best practices for alert management:
- Set maintenance windows. Suppress alerts during planned maintenance so your team is not paged for a scheduled update or migration.
- Use tiered notifications. Urgent alerts for hard failures go to on-call contacts immediately. Performance degradations, such as slow response times, go into a digest report reviewed at the start of the working day.
- Route alerts by severity. A checkout page failure warrants an immediate SMS or phone call. A blog page going slow warrants an email.
- Review alert history monthly. If a monitor fires frequently without a genuine incident, the threshold or retry count needs adjusting.
- Avoid alerting on a single failed check. Paging on one failure creates false-positive disruptions that erode team confidence in the monitoring system.
Effective alerting reduces operational stress by prioritising incidents that actually need a response. The goal is not to know about every blip. The goal is to know immediately when something is genuinely broken.
Common pitfalls in uptime monitoring setups
The most frequent mistake in website downtime tracking is trusting HTTP status codes too much. A 200 OK response confirms the server answered. It does not confirm the page is functional, the content is correct, or the user experience is intact. Keyword monitoring is the fix. Choose a string of text that only appears on a healthy version of the page and verify its presence on every check.
Single-location monitoring is the second most common error. If your monitoring node and your hosting server share a network path, a failure on that path looks like a site outage when it is not. Always use at least three geographically separate check locations before drawing conclusions about availability.
Configuration drift is a quieter problem. Sites evolve. New pages launch, checkout flows change, and SSL certificates renew on different schedules. A monitoring setup built at launch and never revisited will miss new critical pages entirely and may still be checking URLs that no longer exist.
Pro Tip: Schedule a monitoring audit every quarter. Check that every monitored URL still exists and returns the correct content. Verify that new high-value pages have been added with appropriate check intervals. Confirm that SSL expiry alerts are set at least 30 days before certificate renewal dates.
The website performance monitoring guide principle applies here too. Uptime and performance are connected. A site that loads in 12 seconds is technically available but practically useless. Include response time thresholds in your monitoring setup so slow pages trigger alerts before users start complaining.
Key takeaways
Effective uptime monitoring requires layered checks, multi-region verification, and alert rules that distinguish genuine outages from transient noise.
| Point | Details |
|---|---|
| Know your uptime tiers | 99.9% allows 8.76 hours of downtime annually; 99.99% allows just 52 minutes. |
| Match check frequency to criticality | Checkout and login pages need 60-second checks; blog pages can run every 5 minutes. |
| Layer your monitoring checks | Add SSL, DNS, keyword, and response time checks beyond basic HTTP status codes. |
| Require multi-region confirmation | Alert only after two consecutive failures from two separate geographic locations. |
| Audit your setup quarterly | Review monitored URLs, thresholds, and alert rules every quarter to prevent configuration drift. |
Uptime monitoring is not a set-and-forget task
The agencies I see struggle most with uptime monitoring are the ones who set it up once, pointed it at the homepage, and assumed the job was done. That approach catches the obvious catastrophic failures. It misses everything else.
The sites that cause the most damage are the ones that appear up but are not working. A checkout that returns 200 OK but silently fails to process payments. A login page that loads but throws a PHP error on submission. A homepage that serves a cached version from three weeks ago. None of these trigger a basic availability alert. All of them cost your client money and cost you credibility.
My recommendation is to treat uptime monitoring as a living system, not a one-time configuration. Start with the critical pages, add keyword checks from day one, and build in the multi-region rule before you go live. Then schedule a quarterly review as a recurring calendar item. The 30 minutes you spend auditing your monitoring setup is worth more than the hours you will spend managing an incident that a better setup would have caught earlier.
Monitoring also belongs inside your broader maintenance plan, not alongside it. If you are running WordPress care plans for clients, uptime data should feed directly into your monthly reporting. Clients who can see their uptime history, response time trends, and SSL status are clients who understand the value of what you provide. That visibility is one of the most underused retention tools in agency account management.
— Marcel
Wpcto handles WordPress uptime monitoring for agencies
Wpcto provides WordPress maintenance and support built specifically for UK design and digital agencies. Uptime monitoring, SSL management, performance checks, and security scanning are all handled as part of our agency care plans, so your team never has to respond to a client’s site going down at 11pm on a Friday. We sit behind your agency invisibly, keeping your clients’ sites running and your team focused on the work that actually generates revenue. If you want to see how much uncaptured revenue is sitting in your existing WordPress client base, the WordPress Profit Calculator gives you the answer in under 90 seconds.
FAQ
What is website uptime monitoring?
Website uptime monitoring is the automated process of regularly checking whether a site is accessible, responsive, and serving correct content. Tools like UptimeRobot and Pingdom run these checks at set intervals and alert you when a failure is detected.
What uptime percentage should I aim for?
The industry standard is 99.9%, which allows approximately 8.76 hours of downtime per year. Mission-critical or e-commerce sites should target 99.99%, which limits downtime to around 52 minutes annually.
How often should uptime checks run?
Checkout and login pages should be checked every 60 seconds. Marketing and blog pages can be checked every 5 minutes. Match the interval to the commercial importance of the page.
Why does a 200 OK status not guarantee my site is working?
A 200 status confirms the server responded, not that the page is functional or serving the correct content. Keyword monitoring, which checks for specific text in the page response, is required to confirm true availability.
How do I reduce false positive alerts?
Set a 10-second timeout threshold with at least two retries before alerting. Require two consecutive failures from two separate geographic locations before triggering an urgent notification. Suppress alerts during planned maintenance windows.