

TL;DR:
- Proper load balancing distributes incoming traffic across multiple servers to prevent overload and maintain uptime. It enhances website performance, scalability, and resilience, especially during traffic surges, by intelligently routing requests and avoiding single points of failure. Misconfigurations, such as incorrect health checks or lack of session stickiness, can increase failures and reduce reliability for WordPress sites.
Most agencies assume that upgrading hosting solves uptime problems. It helps, but it rarely tells the whole story. The real question is what happens to incoming requests once they arrive at your infrastructure. When traffic spikes, a single overloaded server will buckle regardless of its specification. Load balancing is the mechanism that prevents this, and for agencies managing multiple WordPress client sites, understanding it properly is the difference between confident service delivery and reactive firefighting.
Table of Contents
- What is load balancing?
- Key components and traffic flow in load balancing
- Comparing common load-balancing algorithms
- Layer 4 vs. Layer 7: Routing approaches explained
- Avoiding common load-balancing pitfalls for agencies
- Load balancing in WordPress agency delivery: High-availability made practical
- Our take: What agencies often miss about load balancing
- How WPCTO supports agencies: Seamless WordPress reliability
- Frequently asked questions
Key Takeaways
| Point | Details |
|---|---|
| Distributes traffic efficiently | Load balancing ensures that no single server becomes a bottleneck by spreading requests across multiple backends. |
| Algorithm choice affects performance | Selecting the right load-balancing algorithm is crucial for optimising latency and user experience. |
| Layer matters in routing | Layer 4 and Layer 7 load balancers use different approaches, impacting how traffic is managed for WordPress sites. |
| Health-aware routing prevents outages | Health checks and dynamic rerouting help maintain uptime by avoiding failed servers. |
| Agency delivery improves client satisfaction | Agencies using robust load balancing can offer faster, more reliable WordPress services to clients. |
What is load balancing?
Load balancing is the practice of distributing incoming traffic across multiple backend servers so no single resource becomes a bottleneck. Rather than one server absorbing every request, a load balancer sits in front of your infrastructure and routes each request intelligently.
For agencies, this matters enormously. A client’s product launch, a PR-driven traffic surge, or a flash sale can send visitor numbers soaring within minutes. Without load balancing, that spike hits one server. With it, the load spreads across several, and the site stays fast and stable.
Core benefits for agencies managing WordPress sites include:
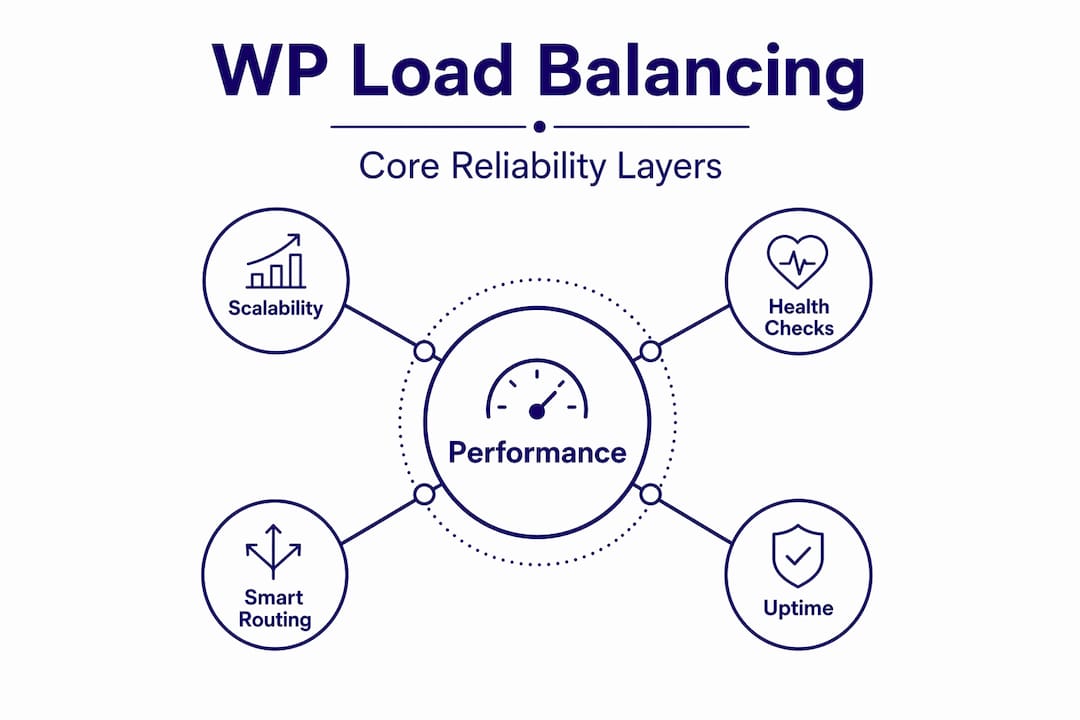
- Improved uptime: Failed servers are bypassed automatically, keeping sites online.
- Better performance: Requests reach the least-burdened server, reducing page load times.
- Scalability: New servers can be added during high-demand periods without disruption.
- Reduced risk: No single point of failure means client incidents are far less likely.
Proper WordPress hosting and maintenance already addresses many reliability concerns, but load balancing adds a structural layer of resilience that hosting configuration alone cannot provide. For agencies that want to offer high-performance WordPress hosting to clients, understanding this distinction is essential.
Load balancing is not simply a technical upgrade. It is a deliberate architectural decision that shapes how reliably your clients’ sites behave under real-world conditions.
Focusing on reducing WordPress downtime starts with understanding that hosting capacity and traffic distribution are two separate problems that both need solving.
Key components and traffic flow in load balancing
A load balancer typically receives a request, applies a routing algorithm to pick a backend, and can include health checking to avoid routing to unhealthy backends. Let’s walk through this step by step.
How a request flows through a load-balanced system:
- A visitor’s browser sends a request to your domain.
- DNS resolves to the load balancer’s IP address, not directly to a web server.
- The load balancer applies its routing algorithm to select a backend server.
- The request is forwarded to the chosen server.
- The server processes the request and returns a response via the load balancer.
- Health checks run continuously in the background, removing unhealthy servers from the pool.
Health checks are critical. Without them, a load balancer will happily route traffic to a server that has crashed or is responding too slowly, which actively worsens the user experience. Most modern load balancers support HTTP health checks, which ping a specific endpoint and expect a valid response within a defined timeout.
| Component | Role | Failure risk if absent |
|---|---|---|
| Load balancer | Routes incoming requests | Single point of failure |
| Backend servers | Process and serve content | Overload on any single server |
| Health checks | Detect unhealthy backends | Traffic routed to failed servers |
| Session management | Maintains user state | Broken logins and cart data |
For agencies managing WordPress hosting and migration, understanding this flow helps when planning site moves or infrastructure upgrades. Poor traffic routing during a migration is a common cause of post-launch instability.
Future-proofing website scalability depends on building this kind of architecture from the start, not retrofitting it after a client incident forces your hand. Agencies that invest in understanding the WordPress tech stack early avoid expensive reactive fixes later.
Comparing common load-balancing algorithms
Common load-balancing algorithms include round robin, weighted round robin, least connections, and least response time, each optimising for different signals. Choosing the wrong one for your traffic pattern is a genuine operational risk.
| Algorithm | How it works | Best for |
|---|---|---|
| Round robin | Rotates requests evenly across servers | Uniform, predictable traffic |
| Weighted round robin | Allocates more requests to higher-capacity servers | Mixed server specifications |
| Least connections | Routes to the server with fewest active connections | Variable request duration |
| Least response time | Routes to the fastest-responding server | Latency-sensitive applications |
For most WordPress agency clients, least connections or least response time deliver the best results. WordPress requests vary considerably in processing time. A logged-in user loading a complex WooCommerce page takes far longer to serve than a cached homepage view. Round robin ignores this entirely and can create hotspots on servers handling heavier requests.
Key considerations when selecting an algorithm:
- E-commerce sites benefit from least response time, as checkout pages are resource-intensive.
- Content-heavy sites with mostly cached output can work well with round robin.
- Sites with mixed server specs should use weighted round robin to avoid overloading smaller instances.
- High-traffic campaigns need algorithms that react to real-time server load, not just request counts.
Pro Tip: If you manage robust e-commerce platforms for clients, test your algorithm choice under simulated load before a major campaign. A misconfigured algorithm under pressure behaves very differently to one under normal traffic.
WordPress site caching works alongside load balancing rather than replacing it. Caching reduces the number of requests that reach the backend, while load balancing ensures those that do are distributed efficiently. Together, they deliver the kind of high-performance web hosting that clients notice and remember.
Layer 4 vs. Layer 7: Routing approaches explained
Load balancers are often classified by OSI layer: Layer 4 focuses on transport-level details (IP/port) while Layer 7 makes HTTP/content-aware routing decisions (headers/URL/cookies) after inspecting application data. This distinction matters practically for agencies.
Layer 4 load balancing:
- Routes based on IP address and port only.
- Does not inspect the content of requests.
- Faster and less resource-intensive.
- Suitable for simple, high-volume traffic distribution.
- Limited ability to handle WordPress-specific routing needs.
Layer 7 load balancing:
- Inspects HTTP headers, URLs, cookies, and content.
- Enables session stickiness (routing a user to the same server consistently).
- Supports content-aware routing, such as sending API requests to dedicated servers.
- Essential for WordPress sites where logged-in users need consistent server sessions.
- Slightly more overhead, but far more flexible for complex agency deployments.
For most WordPress agency work, Layer 7 is the right choice. WordPress relies on session data for logged-in users, WooCommerce carts, and form submissions. Without session stickiness at Layer 7, a user’s session can break mid-journey if their requests land on different servers.
Pro Tip: When securing WordPress sites at the infrastructure level, Layer 7 load balancers can also inspect and filter malicious requests before they reach your web servers, adding a meaningful security layer alongside WordPress site reliability improvements. Some providers integrate web application firewall (WAF) functionality directly into Layer 7 balancers, which is worth exploring for client sites handling sensitive data. Practical WordPress security steps often begin at this infrastructure level rather than at the plugin layer.
Avoiding common load-balancing pitfalls for agencies
Load-balancing misconfigurations or blind traffic routing can increase failures, for example, sending traffic to overloaded or slow backends, setting incorrect health checks, or failing to drain connections during deploys. This is where many agencies get caught out.
Common pitfalls to avoid:
- Incorrect health check thresholds: A health check that times out too quickly will mark healthy servers as failed, reducing your available pool unnecessarily.
- Missing connection draining: During a deployment, failing to drain active connections from a server before taking it offline causes in-flight requests to fail visibly.
- Ignoring session stickiness for WordPress: Without sticky sessions on a Layer 7 balancer, logged-in WordPress users can experience broken sessions and lost cart data.
- No monitoring or alerting: Load balancing without visibility is dangerous. You need to know when a backend drops out of rotation and why.
- Treating load balancing as a set-and-forget system: Traffic patterns change, server capacity changes, and your configuration needs to keep pace.
Pro Tip: Build a simple runbook for your team covering what to check when a client site goes slow under load. This should include load balancer logs, backend health status, and active connection counts. The WordPress maintenance best practices that prevent most incidents are procedural, not just technical.
Offloading WordPress maintenance to a specialist partner removes the burden of monitoring these systems from your team entirely. A comprehensive WordPress maintenance guide will always include infrastructure monitoring as a core element, not an afterthought.
Load balancing in WordPress agency delivery: High-availability made practical
Agencies commonly aim for high availability via redundant web servers and load balancing to distribute traffic and reroute when instances fail. In practice, this means running at least two web server instances behind a load balancer, with a shared database and file storage layer.
What this looks like for agency client delivery:
- Automatic failover: If one server instance fails, the load balancer removes it from rotation and remaining servers absorb the traffic without client-visible disruption.
- Zero-downtime deployments: New code can be deployed to one server at a time while the others continue serving traffic.
- Traffic surge handling: Additional instances can be spun up during campaigns and removed afterwards, keeping costs proportionate.
- Faster incident recovery: When something goes wrong, the load balancer contains the blast radius by isolating the affected server.
Clients notice the results rather than the mechanism. They experience faster pages, fewer errors during busy periods, and quick recovery when issues do occur. For agencies, this translates directly into fewer emergency calls, stronger client retention, and a more confident service proposition.
Reducing WordPress downtime at this infrastructure level is what separates agencies that genuinely deliver reliability from those that simply hope for the best. WordPress e-commerce clients in particular depend on this kind of resilience, where every minute of downtime has a measurable revenue cost.
Our take: What agencies often miss about load balancing
Most agencies, when they think about load balancing at all, treat it as a hosting provider’s problem. They assume that choosing a managed WordPress host with good uptime guarantees covers the requirement. It often does not.
The real gap is in policy and monitoring. Adding more servers without configuring the right algorithm, health checks, and session handling can actually make things worse. We have seen agencies deploy load-balanced infrastructure and then experience more incidents than before, purely because the configuration was never validated under realistic traffic conditions.
Algorithm choice is genuinely consequential. A round-robin setup on a WooCommerce site with variable page complexity will create uneven server load during peak traffic. Switching to least connections or least response time often resolves performance complaints that were previously blamed on plugins or themes.
Health-aware routing gives you resilience that goes well beyond basic uptime monitoring. A server can be technically online but responding in four seconds. Without proper health check thresholds, your load balancer will keep sending it traffic while users experience a degraded site. This is the kind of subtle failure that damages client trust without triggering an obvious alert.
The agencies that get this right treat load balancing as part of their service quality commitment, not a backend detail. They invest in understanding the architecture, or they partner with someone who does. Either way, reducing WordPress downtime at scale requires deliberate infrastructure decisions, not just better hosting plans.
How WPCTO supports agencies: Seamless WordPress reliability
Understanding load balancing is one thing. Having the infrastructure, expertise, and monitoring in place to deliver it consistently for every client is another challenge entirely.
At WPCTO, we handle the full WordPress delivery stack for agencies across the UK, including hosting management, performance optimisation, security monitoring, and emergency support. Our WordPress agency services are built specifically for creative and digital agencies who want to offer reliable, high-performance WordPress to their clients without managing the technical complexity themselves. Our white label WordPress support means your clients see your brand, not ours. You keep the relationship and the recurring revenue. We handle everything behind the scenes. Use our WordPress Profit Calculator to see exactly how much uncaptured revenue is sitting in your current client base.
Frequently asked questions
How does load balancing increase website reliability?
Load balancing distributes traffic evenly across multiple servers and reroutes requests automatically if a server fails, significantly reducing the risk of downtime.
Which load-balancing algorithm is best for WordPress sites?
For most WordPress sites, least connections or least response time algorithms deliver better performance by responding to real-time server load and latency rather than simply rotating requests.
What is the difference between Layer 4 and Layer 7 load balancers?
Layer 4 balances traffic using IP and port details only, while Layer 7 inspects application data such as HTTP headers, URLs, and cookies to make more intelligent routing decisions.
Can misconfigured load balancing cause more failures?
Yes. Blind routing and incorrect health checks can actively amplify outages by continuing to send traffic to overloaded or unhealthy backend servers.