

TL;DR:
- Optimizing a website’s loading workflow improves performance and increases conversion rates.
- Key steps include fixing server TTFB, inline critical CSS, and implementing tiered caching.
A website’s loading workflow is defined as the sequence in which a browser requests, receives, and renders resources, from the first HTML byte to the final painted pixel. Getting that sequence right is not a cosmetic concern. Websites loading in one second convert at three times the rate of five-second loads, and a 0.1-second mobile speed improvement raises conversions by 8.4%. Those numbers make performance a revenue decision, not just a technical one. For web developers and digital agency owners, understanding how to improve website loading workflow across every layer, from server response to asset delivery, is the difference between a site that earns and one that leaks.
What are the essential prerequisites for improving website loading workflow?
Before touching a single line of code, you need accurate data. Real user monitoring (RUM) and the Chrome User Experience Report (CrUX) tell you how actual visitors experience your site. Lab tools like Lighthouse and the Chrome DevTools coverage panel show you what is happening under controlled conditions. You need both. CrUX field data lags by 28 days, so lab tools give you faster feedback during active optimisation work.
The four metrics that matter most are Time to First Byte (TTFB), Largest Contentful Paint (LCP), Interaction to Next Paint (INP), and Cumulative Layout Shift (CLS). These are the Core Web Vitals that Google uses to assess page experience. Fixing them in the wrong order wastes time. A TTFB above 600ms limits the effectiveness of every frontend fix you apply. Sort your server response time first.
Here is a baseline setup checklist before you begin:
- Confirm your hosting environment supports server-side caching and HTTP/2 or HTTP/3
- Install a build tool (Webpack, Vite, or Parcel) to handle asset bundling and code splitting
- Set up Lighthouse CI or a similar automated audit in your deployment pipeline
- Connect your site to CrUX via Google Search Console or the CrUX API
- Identify your three highest-traffic pages using Google Analytics or equivalent RUM data
| Metric | Target threshold | Tool to measure |
|---|---|---|
| TTFB | Below 200ms | Chrome DevTools, WebPageTest |
| LCP | Below 2.5 seconds | Lighthouse, CrUX |
| INP | Below 200ms | CrUX, RUM tools |
| CLS | Below 0.1 | Lighthouse, CrUX |
Pro Tip: Run your Lighthouse audit in incognito mode with browser extensions disabled. Extensions inflate JavaScript execution times and produce misleading scores.
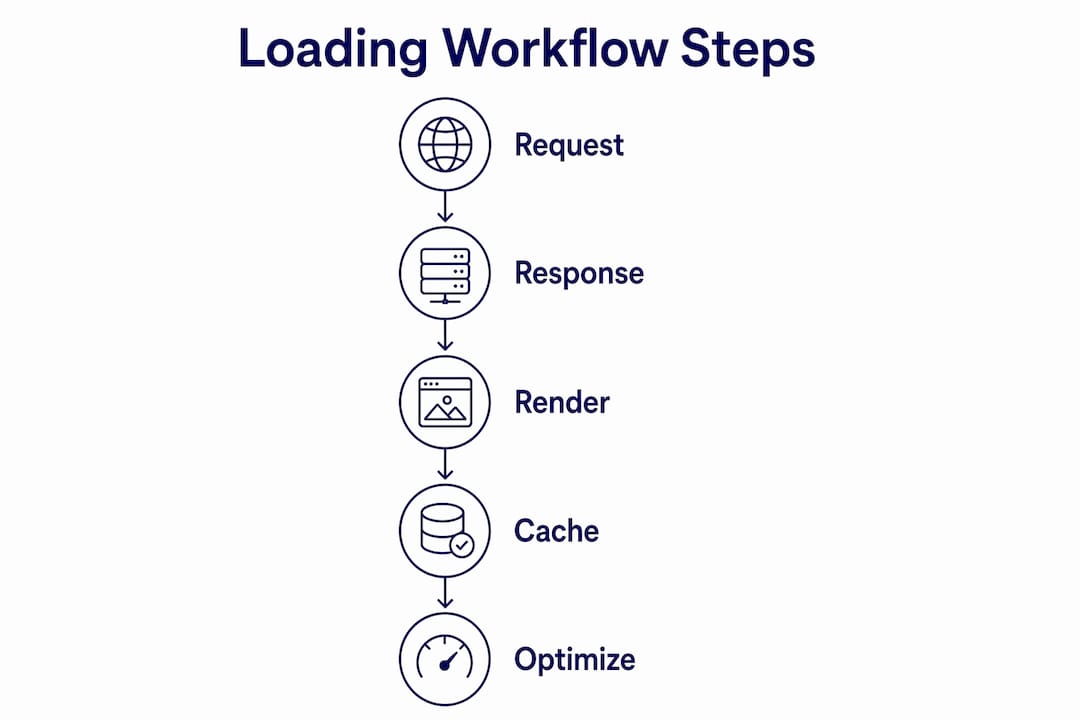
How does critical CSS inlining reduce LCP?
Critical CSS inlining is the practice of extracting the styles needed to render above-the-fold content and placing them directly inside the HTML <head>. The browser can then paint the visible page without waiting for an external stylesheet to download. Inlining 15–20KB of critical CSS reduces LCP by 800ms to 1.2 seconds. That is a meaningful gain from a single, well-targeted change.
The implementation follows a clear sequence:
- Use a tool like Critical (the Node.js package) or PurgeCSS to extract the styles applied to above-the-fold elements on your key pages.
- Paste the extracted CSS directly into a
<style>block in the<head>of your HTML. - Load the full stylesheet asynchronously using
<link rel="preload" as="style">with anonloadhandler that switches it to a standard stylesheet once downloaded. - Add a
<noscript>fallback linking the stylesheet normally for browsers with JavaScript disabled. - Set
fetchpriority="high"on your hero image or the element most likely to be your LCP candidate.
Resource prioritisation does not stop at CSS. Critical fonts should be preloaded using rel="preload" and rendered with font-display: optional or font-display: swap to prevent invisible text (FOIT) and layout reflow (FOUT). Font subsetting, loading only the character ranges your site actually uses, cuts font file sizes dramatically and is far more impactful than generic minification.
One point that catches many developers out: never apply loading="lazy" to your LCP element. Lazy loading the hero image adds a 200–500ms delay because the browser deprioritises it until it enters the viewport. Use fetchpriority="high" instead to signal that this resource needs to load immediately.
Pro Tip: After inlining critical CSS, use the Chrome DevTools coverage panel to identify unused CSS in your full stylesheet. Removing unused rules before async loading reduces the payload your visitors download on every page visit.
For a broader look at site speed best practices across the full stack, the Wpcto insights library covers the topic in depth.
How can a tiered caching hierarchy enhance your loading workflow?
Caching is the single highest-leverage backend change most sites never fully implement. A properly configured tiered cache hierarchy, working in the order edge cache, reverse proxy, application cache, and database cache, can reduce server load by 10 to 100 times. That reduction means faster responses for every user, not just those on fast connections.
Each layer serves a distinct purpose. The edge cache (a CDN like Cloudflare or Fastly) answers requests before they reach your origin server. The reverse proxy (Nginx or Varnish) handles requests that miss the edge. The application cache (object caching via Redis or Memcached) stores the results of expensive database queries. The database cache itself uses query caching to avoid repeated reads of the same data.
| Cache layer | Technology examples | What it caches |
|---|---|---|
| Edge cache | Cloudflare, Fastly | Full HTML pages, static assets |
| Reverse proxy | Nginx, Varnish | Dynamic page output |
| Application cache | Redis, Memcached | Database query results, sessions |
| Database cache | MySQL query cache | Repeated read queries |
Cache-Control headers govern how long each layer holds a response. Static assets like images and fonts should carry long max-age values (one year is standard) combined with content-hash filenames so that a new deploy automatically busts the cache. Dynamic HTML typically needs a shorter TTL or must be purged explicitly on content updates.
Pro Tip: Do not apply caching to pages that contain personalised content, such as logged-in dashboards or checkout pages, without a cache-bypass rule. Serving a cached page with another user’s data is both a privacy risk and a support headache.
What are the most common mistakes in load speed optimisation?
The most damaging mistake is applying frontend fixes to a site with a slow server. A TTFB above 600ms undermines every other optimisation. Inlining critical CSS on a server that takes 800ms to respond still produces a slow LCP. Fix hosting and infrastructure first, then layer frontend improvements on top.
The second most common error is spending time on changes that do not move the needle. Minification typically saves around 2KB. That is not nothing, but it is not the reason your LCP is at 4.2 seconds. Font subsetting, eliminating long main-thread tasks, and targeting the specific LCP element deliver far larger gains.
A few other pitfalls to avoid:
- Lazy loading LCP elements. As noted above, this adds 200–500ms of delay. Check every hero image and above-the-fold video on your key pages.
- Optimising for lab averages instead of the 75th percentile. Google’s Core Web Vitals thresholds are assessed at the 75th percentile of real user sessions. A site that performs well for the average user but poorly for the slowest quarter will still fail the assessment.
- Treating all pages equally. Your homepage and top landing pages drive the most revenue. Optimise those first. A deep archive page with 12 monthly visits does not need the same attention.
“Real performance comes from combined frontend, backend, database, network, and cache adjustments, not just frontend tricks.”
For a structured approach to finding these issues before they compound, a WordPress performance audit is the most reliable starting point.
How do you measure and verify loading workflow improvements?
Measurement is where most optimisation projects fall apart. Developers make changes, run a Lighthouse audit, see a score improvement, and ship. The problem is that Lighthouse is a lab tool. It runs under controlled conditions that do not reflect the range of devices, connections, and locations your actual users have.
Use this verification sequence:
- Run a Lighthouse audit immediately after each change to confirm the fix had the expected lab-level effect.
- Check Chrome DevTools waterfall charts to confirm resource load order matches your intended priority sequence.
- Wait for CrUX data to update (the 28-day field data lag means you need patience) and then review 75th percentile LCP, INP, and CLS for your key pages.
- Set up automated Lighthouse CI alerts in your deployment pipeline so regressions trigger a notification before they reach production.
- Cross-reference lab improvements with RUM data from your analytics platform to confirm real users are experiencing the gains.
The 75th percentile focus is not optional. CrUX data at the 75th percentile reflects the experience of your slower users, the ones most likely to leave. Optimising for the median while ignoring the tail means you are improving the experience for people who were already satisfied.
If you are working across multiple client sites, the WordPress performance troubleshooting guide from Wpcto covers how to bridge lab results with real-user data systematically.
Key takeaways
Improving website loading workflow requires fixing server TTFB first, then applying layered frontend and caching optimisations, and verifying results against 75th percentile CrUX data rather than lab averages alone.
| Point | Details |
|---|---|
| Fix TTFB before frontend work | Server response above 600ms limits every frontend gain; target below 200ms first. |
| Inline critical CSS | Extracting 15–20KB of above-the-fold styles reduces LCP by up to 1.2 seconds. |
| Never lazy load LCP elements | Applying lazy loading to hero images adds 200–500ms delay; use fetchpriority=“high” instead. |
| Build a tiered cache hierarchy | Edge, reverse proxy, application, and database caching together can cut server load by up to 100 times. |
| Measure at the 75th percentile | CrUX field data lags 28 days; focus on the 75th percentile, not the average, for accurate assessment. |
What I have learned from years of performance work
The agencies I work with most often arrive with the same problem. They have run a Lighthouse audit, scored 62, installed a caching plugin, and scored 74. Then they stop, because the score looks better. Six months later, a client complains that their site feels slow on mobile. The score and the experience have diverged.
The uncomfortable truth about load speed optimisation is that plugins do not fix infrastructure. A caching plugin on a shared hosting plan with a 900ms TTFB is a plaster on a structural problem. The real gains come from moving to managed hosting with proper server-side caching, then applying code-level changes on top. That order matters enormously.
I also see agencies focus their optimisation effort on the wrong pages. They spend hours on the blog archive or the about page, while the homepage and the main service landing pages, the pages that actually drive enquiries, sit untouched. Start with your highest-traffic, highest-revenue pages. The WordPress optimisation strategies that move the needle are always page-specific, not site-wide.
The most disciplined teams I have worked with treat performance as a continuous loop, not a one-off project. They audit, fix, measure, and repeat. They do not chase a perfect score. They chase a better experience for the users who matter most to the business.
— Marcel
How Wpcto supports your performance workflow
Managing performance across a portfolio of client WordPress sites is a different challenge to fixing one site. The diagnostic work, the hosting conversations, the plugin conflicts, the cache invalidation issues: all of it adds up to hours your team is not spending on creative or strategic work.
Wpcto handles the full WordPress performance and maintenance layer for digital agencies, covering hosting management, performance optimisation, security monitoring, and plugin management. Agencies keep the client relationship and the recurring revenue. Wpcto handles the technical delivery. If you want to see how much uncaptured revenue is sitting in your existing WordPress client base, the WordPress Profit Calculator gives you a clear answer in under 90 seconds. For agencies ready to hand off the technical work entirely, the Wpcto agency services page sets out exactly how the partnership works.
FAQ
What is a website loading workflow?
A website loading workflow is the sequence in which a browser requests and renders resources, from the initial HTML response through to the final painted element. Optimising this sequence reduces load times and improves Core Web Vitals scores.
Why does TTFB matter before frontend optimisation?
A TTFB above 600ms limits the effect of every frontend fix applied afterwards. Reducing TTFB below 200ms through better hosting or server-side caching creates the foundation that frontend improvements build on.
What is the fastest way to improve LCP?
Inlining 15–20KB of critical CSS and setting fetchpriority="high" on the hero image are the two changes that consistently deliver the largest LCP reductions, often cutting 800ms to 1.2 seconds from load time.
How long does it take to see real user data after making changes?
CrUX field data has a 28-day lag, so changes made today will not appear in field reports for approximately four weeks. Use Lighthouse and Chrome DevTools for immediate feedback during active optimisation work.
Is minifying CSS and JavaScript worth the effort?
Minification is worth doing as part of a build process, but it delivers negligible performance gains on its own. Font subsetting, eliminating long main-thread tasks, and fixing LCP element prioritisation produce far larger improvements.