

TL;DR:
- Proactive monitoring, resilient deployment practices, and managing third-party dependencies significantly reduce website downtime. Implementing staged alerts, automated rollback, and clear incident response procedures ensures faster recovery and higher site reliability. Building a culture of prevention and transparent communication is essential for long-term uptime management.
Website downtime is defined as any period when a site is unavailable to users, whether for seconds or hours, and the most effective way to reduce it is through proactive monitoring, automated alerts, and resilient deployment practices. Tools like UptimeRobot, status pages, and circuit breakers for third-party APIs form the foundation of any serious uptime strategy. The uncomfortable truth is that most avoidable downtime is caused by expired SSL certificates, lapsed domain names, and full server disks rather than dramatic cyberattacks. Understanding that shifts your entire approach. You stop reacting to outages and start removing the conditions that cause them.
What are the essential tools to minimise website downtime?
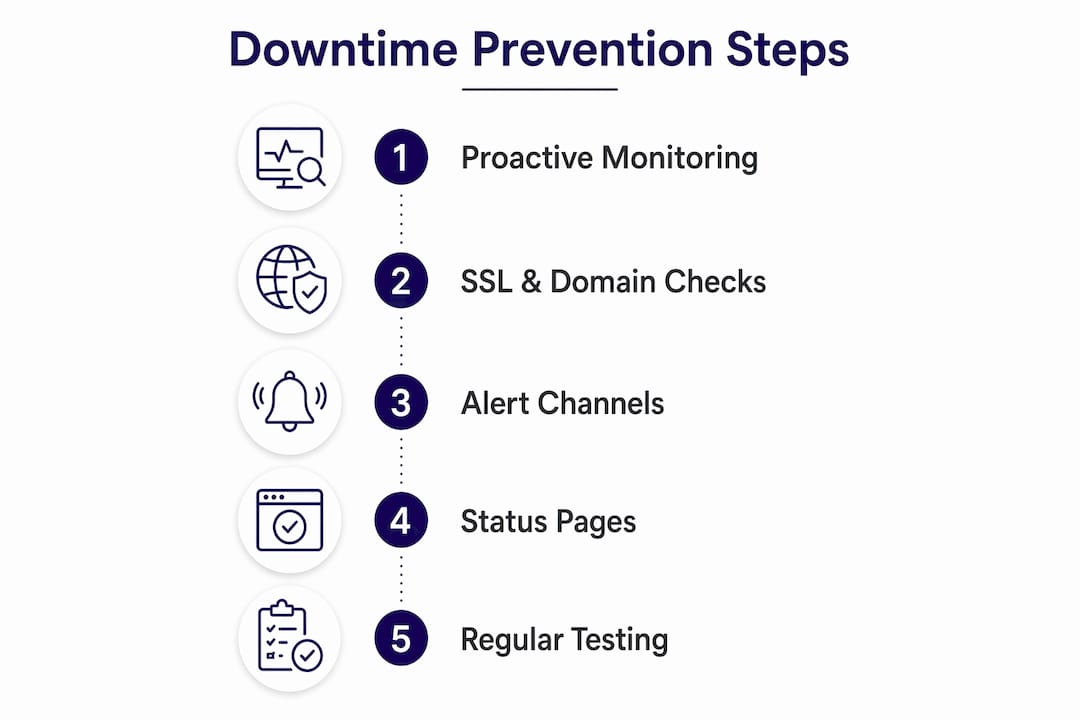
Proactive uptime monitoring with checks every 1–5 minutes from multiple geographic locations is the single most effective first step. It catches failures before your clients or their customers notice anything. A single monitoring point is not enough. Multi-region monitoring identifies regional outages that a single check location would miss entirely.
Beyond basic uptime checks, you need independent monitoring for SSL certificates and domain names. Administrators should set expiry alerts at 30, 14, 7, and 1 day before each renewal deadline. That four-stage alert schedule gives you multiple chances to act before a certificate lapses and takes a site offline. Missing a single renewal is one of the most embarrassing and entirely preventable causes of downtime.
Alert channels matter as much as the monitoring itself. Email alone is too slow for a live incident. Route critical alerts through SMS and a team channel in Slack or Microsoft Teams so the right person sees the notification within minutes, not hours.
A public status page is the final piece of the monitoring toolkit. It lets you acknowledge an outage immediately, even before you know the cause, which protects client trust during the worst moments.
Pro Tip: Test your alert pipeline monthly. Send a deliberate test alert and confirm every channel receives it. Monitoring tools that silently fail are worse than no monitoring at all.
Here is a quick reference for the core tools and their primary function:
| Tool type | Primary function |
|---|---|
| Uptime monitor (e.g. UptimeRobot) | Checks site availability every 1–5 minutes from multiple locations |
| SSL and domain expiry monitor | Sends staged alerts at 30, 14, 7, and 1 day before expiry |
| Status page (e.g. Statuspage) | Communicates outage status publicly and honestly |
| Alert routing (Slack, SMS, email) | Delivers notifications to the right person fast |
| Load balancer | Distributes traffic and removes single points of failure |
For a deeper look at building a monitoring process that holds up in practice, the uptime monitoring guide from Wpcto covers the 2026 recommendations in full.
How to execute resilient deployment practices to prevent downtime
Deployment is the single most common trigger for unplanned outages. A working site goes down because a code push introduced a bug, a database migration broke compatibility, or a plugin update conflicted with the theme. Every one of those scenarios is preventable.
Follow these steps to build a deployment process that protects uptime:
- Automate builds with mandatory rollback. Automated builds with rollback capability are a standard practice in 2026. If a deployment fails a health check, the system reverts automatically without waiting for a human to notice.
- Use backward-compatible database migrations. Never run a migration that breaks the previous version of the application. Deploy the code first, migrate the database second, and keep the old schema readable until the new version is confirmed stable.
- Set disk space alerts at 80% capacity. Disk space alerts at 80% prevent database crashes and failed background jobs before they happen. A full disk is a silent killer that monitoring teams frequently overlook.
- Reduce DNS TTLs before changes. Setting a DNS TTL of 300 seconds before any DNS update means fixes propagate globally within minutes rather than hours if something goes wrong.
- Deploy during low-traffic windows. Schedule releases for periods when traffic is lowest. For most UK business sites, that means late evening or early weekend morning.
- Use load balancing and auto-scaling. Automated recovery actions such as restarting crashed services or scaling resources during traffic spikes reduce downtime without any manual intervention.
Pro Tip: Run a pre-deployment checklist every time, no matter how small the change. The “quick fix” that skips the checklist is the one that takes a site down on a Friday afternoon.
Modern CI/CD pipelines make steps one through five straightforward to automate. If your agency is still deploying manually via FTP, the risk of human error is significant and entirely unnecessary in 2026.
If you want to see how much unresolved downtime risk is sitting in your existing client base right now, the WordPress Profit Calculator shows you in under 90 seconds.
How to manage third-party dependencies to reduce site downtime
Third-party API failure is one of the most underestimated risks in web management. Payment gateways, authentication providers, CDN services, and marketing APIs all sit outside your control. When they fail, your site can fail with them unless you have built in protection.
The key practices for managing external dependencies are:
- Implement circuit breakers. Circuit breakers for critical integrations detect when an external service is failing and trip a fallback mechanism instead of letting the failure cascade through your site. This is standard practice for payment, authentication, and API dependencies.
- Build graceful degradation. Define what your site does when a third-party service is unavailable. A checkout that shows a clear error message and retains the cart is far better than a blank page or a 500 error.
- Cache third-party responses. Where the data does not need to be real-time, cache API responses locally. A cached product feed or exchange rate is better than a broken page caused by an upstream timeout.
- Monitor external services independently. Do not assume a third-party service is up because your site appears to be running. Monitor the APIs your site depends on directly, using tools like API Status Check or similar services.
- Subscribe to vendor status pages. Stripe, Cloudflare, Google, and most major providers publish status pages. Subscribe to their incident notifications so you know about upstream problems before your clients do.
Well-architected sites treat every third-party integration as a potential failure point and build accordingly. The agencies that get caught out are the ones that assume their dependencies are reliable because they have been reliable so far.
What are best practices for incident response after a downtime event?
Fast, structured incident response is what separates a five-minute outage from a two-hour one. The steps below apply whether you are managing the site directly or coordinating with a support partner.
- Verify from multiple networks. Confirm the outage is real and not a local network issue by checking from a mobile connection, a different browser, and an external monitoring tool simultaneously.
- Acknowledge immediately on your status page. Acknowledging outages immediately on a public status page, even before the cause is known, maintains user trust and reduces inbound support requests.
- Diagnose via logs and recent changes. Check error logs, review recent deployments, and look at error rate spikes. The cause is almost always a recent change or a resource limit being hit.
- Mitigate first, investigate second. Roll back the last deployment or scale the server resource before spending time on root cause analysis. Getting the site back online is the priority.
- Update the status page every 15–30 minutes. Regular status updates during an incident, even to say “we are still investigating,” demonstrate that someone is actively working on the problem.
- Verify recovery fully before closing the incident. Check all critical user journeys, not just the homepage. Confirm monitoring alerts have cleared.
- Conduct a blameless post-mortem. Blameless post-mortems that document the root cause and precise prevention steps are the mechanism by which well-managed sites achieve higher uptime over time.
“The goal of a post-mortem is not to find who made the mistake. It is to find what conditions made the mistake possible, and then remove those conditions.”
For agencies managing multiple WordPress client sites, the real cost of site downtime for UK businesses makes a compelling case for investing in this kind of structured response process.
Key takeaways
Reducing website downtime requires proactive monitoring, resilient deployments, managed third-party dependencies, and a structured incident response process working together.
| Point | Details |
|---|---|
| Monitor every 1–5 minutes | Use tools like UptimeRobot from multiple geographic locations to catch failures early. |
| Set staged expiry alerts | Alert on SSL and domain renewals at 30, 14, 7, and 1 day before expiry to prevent avoidable outages. |
| Automate deployments with rollback | Mandatory rollback capability and backward-compatible migrations protect against deployment-caused downtime. |
| Protect against third-party failures | Implement circuit breakers and caching so external API failures do not crash your site. |
| Run blameless post-mortems | Document root causes and prevention steps after every incident to reduce recurrence over time. |
What I have learned from years of managing WordPress uptime
The agencies that have the fewest downtime incidents are not the ones with the most expensive infrastructure. They are the ones that have removed the preventable causes systematically and built a culture where monitoring is treated as a first-class responsibility, not an afterthought.
The most common downtime events I see are not server failures or DDoS attacks. They are expired SSL certificates, a plugin update pushed on a Friday afternoon without a staging test, and a disk that filled up because nobody set an alert. Every one of those is a process failure, not a technical one.
Building a prevention culture through regular monitoring reviews, alert testing, and simulated failure drills matters more than any single tool. I would rather work with a team that tests their rollback process monthly than one that has bought the most expensive monitoring platform but never checks whether the alerts actually fire.
Transparent communication during outages is also underrated. Clients who receive a clear, honest status update within five minutes of an incident are far more forgiving than clients who discover the problem themselves and then cannot reach anyone. That single habit, more than any technical measure, protects the agency relationship.
The DevOps and SRE practices that large engineering teams use are increasingly accessible to smaller agencies and their WordPress clients. The barrier is not technical complexity. It is deciding to treat uptime as something you manage deliberately rather than something that just happens.
— Marcel
How Wpcto helps agencies maintain reliable WordPress sites
Managing WordPress uptime across a client portfolio is time-consuming work that pulls agency teams away from the creative and strategic projects they were hired to deliver. Wpcto handles that work on your behalf.
Our agency WordPress maintenance services cover proactive uptime monitoring, SSL and domain expiry management, plugin and theme updates, security monitoring, and emergency support. We operate as your invisible WordPress partner, so your clients get reliable, well-maintained sites and your team never has to field a Sunday evening support call. We also offer white-label WordPress support for agencies who want to deliver maintenance services under their own brand. Use the WordPress Profit Calculator to see exactly how much recurring revenue your current client base could generate in under 90 seconds.
FAQ
What monitoring frequency is recommended to prevent downtime?
Checks every 1–5 minutes from multiple geographic locations is the recommended standard. This frequency allows early detection before users report issues.
How far in advance should I set SSL certificate alerts?
Set alerts at 30, 14, 7, and 1 day before expiry. This staged schedule gives multiple opportunities to renew before the certificate lapses and takes the site offline.
What is a circuit breaker in the context of website uptime?
A circuit breaker detects when a third-party service is failing and activates a fallback response instead of allowing the failure to crash the site. It is particularly important for payment, authentication, and CDN integrations.
How often should I update a status page during an active incident?
Update the status page every 15–30 minutes during an incident, even if there is no new resolution to report. Regular updates reduce inbound support requests and maintain client trust.
What is a blameless post-mortem and why does it matter?
A blameless post-mortem is a structured review after an incident that documents the root cause and prevention steps without assigning personal blame. It is the primary mechanism for reducing incident recurrence over time.