

Uptime monitoring is the continuous process of checking whether your website is accessible, responding correctly, and serving real content to visitors. Get it right and you know about problems before your clients do. Get it wrong and you find out from an angry email at 9 PM on a Friday. The core of effective website uptime tracking comes down to four layers: HTTP status checks, content validation, SSL certificate monitoring, and DNS health. Each layer catches a different class of failure.
- HTTP checks confirm your server responds with a healthy status code
- Content validation verifies the page actually contains what it should, not a blank screen or error message
- SSL monitoring tracks certificate expiry before it silently breaks every visitor’s browser
- DNS checks confirm your domain resolves to the right address
Production sites need checks every 30–60 seconds, while marketing sites can run at 5–15 minute intervals without meaningful risk. Alerting matters just as much as the checks themselves: email, SMS, Slack, and webhook notifications each serve different urgency levels.
What types of uptime monitoring actually cover
Not all monitoring methods catch the same failures. Understanding the differences helps you build coverage without gaps.
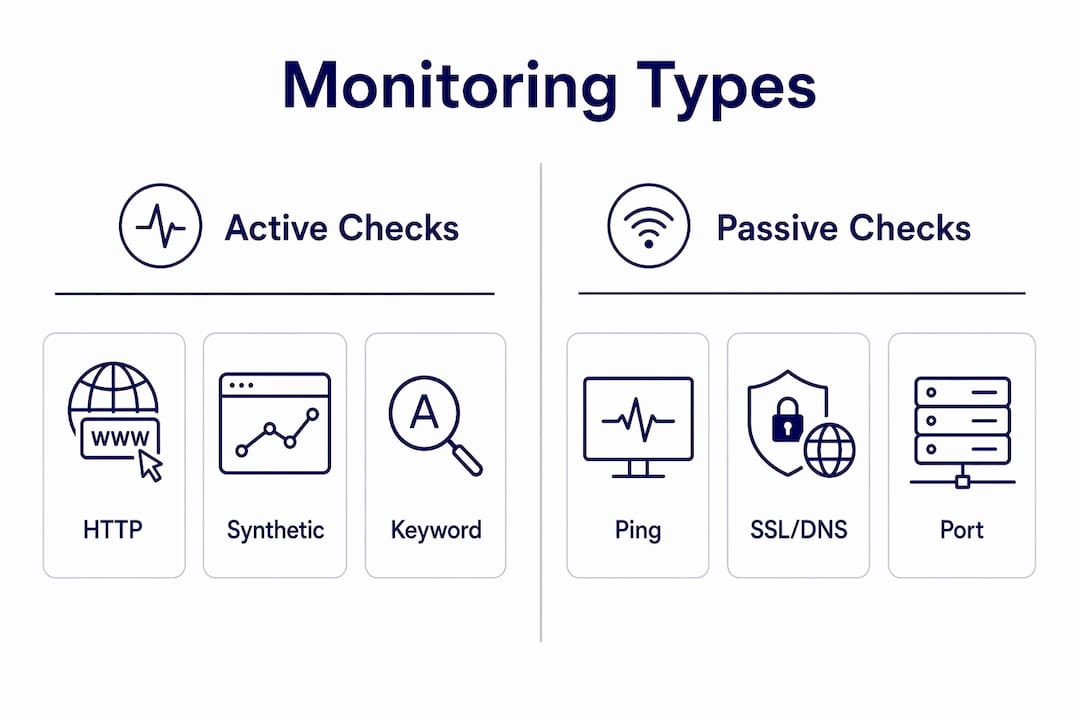
HTTP monitoring is the foundation. It sends a real request to your URL and evaluates the response: status code, response time, and whether the body contains expected content. A 200 OK with a blank page is still a failed check. Status 200 with no content assertion passes the check and dies in production.
Ping monitoring confirms a server is powered on at the network layer. It says nothing about your web server, application, or database. A site can answer ping perfectly while serving a 500 error to every visitor. Use ping as a supplement, never as your primary check.
Keyword and content monitoring goes one step further than HTTP checks. It verifies the response body contains a specific string, such as your company name, a product title, or a footer element. This catches scenarios where the server responds but the application is broken, or a CDN is serving a cached error page.
Advanced monitoring types include:
- SSL certificate monitoring: tracks expiry dates and alerts at 30, 14, and 7 days before expiry. Auto-renewal can fail silently due to DNS changes or rate limits, so monitoring remains necessary even with Let’s Encrypt.
- DNS monitoring: checks that A, AAAA, CNAME, and MX records resolve to expected values. DNS issues are the easiest to miss and the most painful to debug after the fact.
- Cron job and heartbeat monitoring: confirms scheduled tasks complete on time, catching silent background failures.
- Synthetic transaction monitoring: simulates full user journeys such as login, add to cart, and checkout, catching integration failures between services that are individually healthy.
Synthetic monitoring runs scripted checks on a fixed schedule from controlled locations, giving consistent data even at 3 AM when no real users are present. Real user monitoring (RUM) captures actual visitor experience. Use synthetic for proactive detection and SLA reporting; use RUM to understand real-world performance.
How to set up uptime monitoring that actually works
A poorly configured monitoring setup generates noise, not signal. These practices separate setups that teams trust from setups that quietly get muted.
Match check frequency to business impact. Production revenue-generating sites warrant frequent checks at short intervals. Standard transactional flows fit 30–60 second intervals. Marketing pages and blogs can sit at 5–15 minutes. Setting everything to 30 seconds on non-critical sites generates unnecessary data and dashboard noise.
Use at least three geographic check locations. Multi-location testing distinguishes real outages from regional network issues. If all regions fail, your origin is down. If one region fails while others pass, you are looking at a CDN, DNS, or routing problem. That distinction changes who you call and how urgently.
Monitor several critical endpoints, not just the homepage. Your homepage may be served from a CDN cache while your application server is completely down. Monitor the endpoints that matter: login pages, checkout flows, API endpoints, and account dashboards.
Configure content validation on every check. Add keyword checks that verify the page contains expected content. If the keyword is missing, the check fails, catching scenarios where the server responds but the application is broken.
Set up SSL and DNS monitoring with advance alerts. Certificate alerts at 7 days only give you a deadline, not a warning. Alert at 30, 14, and 7 days. For DNS, alert when records change unexpectedly.
Build a tiered alert escalation policy. Immediate alerts go to Slack or a messaging channel. If unacknowledged after 10 minutes, escalate to the team lead. After 20 minutes, escalate further with SMS to a senior engineer.
Pro Tip: Review your monitoring configuration monthly. Delete any alert that fired more than three times without requiring action. If precision drops below a reasonable threshold of real incidents versus false positives, fix the noisiest alerts before adding new ones.
Popular uptime monitoring tools available to UK users
Several well-regarded tools cover the full monitoring stack described above, and all are accessible to UK-based teams.
UptimeRobot is one of the most widely used entry-level tools. Its free tier covers HTTP, ping, keyword, and port monitoring with 5-minute check intervals. Paid plans drop intervals to 60 seconds and add SSL monitoring, multi-location checks, and status page support. It integrates with Slack, email, webhooks, and SMS, making it a practical starting point for individual site owners and smaller agencies.
Uptrends is a more capable platform built for teams that need granular control. It supports HTTP, HTTPS, DNS, SSL, and full-page performance monitoring from a large network of global checkpoints, including multiple UK and European locations. Uptrends offers detailed SLA reporting, white-label status pages, and alert routing with escalation policies. For agencies managing multiple client sites, the multi-user account structure and branded reporting make it a strong fit.
Beyond these two, the broader market includes platforms that specialise in synthetic transaction monitoring, API endpoint checks, and enterprise-grade incident management. When evaluating any tool, the factors that matter most are:
- Number and location of check nodes, particularly UK and European coverage
- Support for content validation, not just status code checks
- SSL and DNS monitoring as standard features
- Alert channel integrations (Slack, PagerDuty, email, SMS, webhooks)
- Status page functionality, including white-label options
- Reporting depth for client-facing SLA documentation
Free tiers are useful for personal projects and low-traffic sites. For production client sites, paid plans with sub-minute intervals and multi-region confirmation are worth the cost.
Common challenges in uptime monitoring and how to handle them
The most common failure in uptime monitoring is not a missing tool. It is a misconfigured one that generates so much noise the team stops paying attention.
Alert fatigue happens when every 30-second network blip pages the team at 3 AM. Within weeks, alerts get muted. Configuring alerts to activate only after multi-location failures reduces noise significantly. The practical rule: require two consecutive failures from two distinct geographies within 60 seconds before paging. A single failed check from one location is almost always a checkpoint hiccup.
Baseline-relative thresholds solve the round-number problem. If your real p95 response time is 4.2 seconds and stable, alerting at “greater than 3 seconds” pages you constantly for normal behaviour. Alert on regional deviation from baseline, not a global average, and require the condition to persist across two consecutive evaluation windows before firing.
Status page confidentiality is a real concern for agencies. Shared public status pages can expose client relationships and infrastructure details. White-labelled individual status pages, branded per client, solve this while still building trust through transparency. Clients see real-time status updates without seeing your other clients.
Monitoring data as a client deliverable is an opportunity most agencies leave on the table. Monthly uptime reports, SSL expiry calendars, and incident summaries transform monitoring from a background cost into visible, documented value. Clients who see the data understand what they are paying for.
Treating uptime monitoring as a proactive intelligence system, with smart alert routing and escalation policies, dramatically reduces false positives and keeps your team focused on incidents that actually require a response.
If you manage WordPress sites for clients and want to understand the full revenue opportunity sitting in your existing client base, the Wpcto WordPress Profit Calculator shows you the numbers in under 90 seconds.
Putting it all together for UK website owners
Effective website uptime monitoring comes down to a handful of decisions made well at the start. Set check intervals that match site criticality. Use at least three geographic locations and require failures from two before alerting. Validate content, not just status codes. Monitor SSL certificates weeks before expiry, not days. Watch DNS records for unexpected changes.
Choose tools that offer UK and European check nodes, white-label status pages, and alert integrations that fit your workflow. UptimeRobot covers the basics at low cost. Uptrends suits agencies that need detailed reporting and multi-client management. For a deeper look at how agencies structure their monitoring approach, the Wpcto guide for digital agencies covers the strategic layer in detail.
The agencies that get the most from monitoring are the ones that use it proactively. They share uptime reports with clients, set SSL renewal reminders months in advance, and treat every incident as data for improving their setup. Monitoring is not a set-and-forget task. It is an ongoing part of delivering reliable WordPress sites.
If your agency handles WordPress maintenance for clients, Wpcto’s agency support services handle the monitoring, maintenance, and emergency response so your team can stay focused on the work you were actually hired to do. And if you want to see exactly how much recurring revenue your current client base could generate, run it through the WordPress Profit Calculator now.
Key takeaways
Effective website uptime monitoring requires multi-region checks, content validation, SSL and DNS monitoring, and alert policies that fire only on confirmed, real incidents.
| Point | Details |
|---|---|
| Check frequency by criticality | Production sites need checks every 30–60 seconds; marketing sites can run at 5–15 minute intervals. |
| Multi-region confirmation | Require failures from at least two geographic locations before triggering an alert to eliminate false positives. |
| Content validation matters | A 200 OK status code does not confirm a working site; always check that expected content is present in the response. |
| SSL and DNS monitoring | Alert on certificate expiry at 30, 14, and 7 days; monitor DNS records for unexpected changes that cause downtime. |
| Alert fatigue prevention | Require two consecutive failures from two distinct locations before paging, and audit alert precision monthly. |