

Stop clicking anything else. Preserve the current state with a screenshot and copy of any error text, then check the site root for a stray .maintenance file and remove it if the update genuinely finished writing files. From there follow a narrow path: check your recovery email and logs, isolate the plugin or theme responsible, repair core files only if needed, and verify before you touch caching or run another update.
TL;DR:
- Deleting the leftover
.maintenancefile from the root often resolves stalled update screens caused by incomplete updates.- Recovery emails specify the plugin or theme causing fatal errors, guiding targeted troubleshooting over manual log analysis.
- Clearing caches before confirming code fixes can hide the real issue, so cache clearing should be done only after verifying the site’s core is stable.
- Manual core repair involves replacing only the
wp-adminandwp-includesdirectories, then running any pending database updates to restore consistency.- Run
WP_DEBUG_LOGand check server logs to identify memory or timeout errors, and request host support if needed to increase PHP limits or restart PHP-FPM.
Table of Contents
- How do I fix WordPress update issues right now?
- What’s actually causing the WordPress update problem?
- Which fixes are safe to try first?
- How do you manually repair WordPress core files?
- Could the hosting environment itself be the problem?
- How do I confirm the site is properly fixed?
- How can agencies prevent this from happening again?
- Should you repair or optimise the database after a failed update?
- What do most agencies get wrong when an update fails?
- Get WordPress update support that doesn’t land on your desk
- Sources
How do I fix WordPress update issues right now?
The first 30 minutes decide whether this is a quick fix or a long afternoon. Work through these in order and test after each one rather than stacking changes.
- Preserve evidence first. Screenshot the error, copy the exact wording, and note the time. If you can reach the file system, grab a quick copy of
wp-contentand export the database before you change anything. - Delete
.maintenancefrom the WordPress root. WordPress creates this file automatically during an update and removes it when the process finishes cleanly. If an update stalls or times out, it’s often left behind, and deleting it is the quickest safe first fix when nothing else is broken underneath. - Clear caches in a controlled order, not immediately. Leave page caching and CDN caching alone until you’ve confirmed the underlying code is fixed, otherwise you’ll mask genuine progress with stale pages.
- Check your inbox for a WordPress recovery email. If one arrived, follow the link straight into Recovery Mode, which tells you exactly which plugin or theme triggered the fatal error and lets you disable it without touching code.
- If wp-admin doesn’t load at all, rename the plugins folder via SFTP (
pluginstoplugins-disabled, for instance). This deactivates every plugin at once so you can get back into the dashboard. - Rename plugins back one at a time, testing the site between each, until the culprit reappears.
- Check disk usage on your hosting panel. A full disk is a common, boring cause of failed updates, and
wp-content/upgrade-temp-backupis worth clearing manually on lower-tier hosting plans where it accumulates partial backups. - Turn on
WP_DEBUG_LOGand readwp-content/debug.logalongside your host’s PHP error log. This is where the actual fatal error lives. - If the logs point to memory or timeouts, contact your host with the exact error line and ask for a PHP-FPM restart or a temporary limit increase, rather than guessing at fixes.
Pro Tip: If you can’t identify the cause within 15 to 20 minutes of calm diagnosis, stop. Don’t re-run the update “to see what happens.” Escalate to your developer or a managed support partner before you compound the problem.
What’s actually causing the WordPress update problem?
Different symptoms point to different failures, and matching them correctly saves you from repairing the wrong thing.
- “Briefly unavailable for scheduled maintenance” stuck on screen almost always means a leftover
.maintenancefile. Remove it and reload before assuming anything worse is wrong. - White screen or “There has been a critical error on this website” usually means a PHP fatal error in a plugin, theme, or occasionally core itself. Recovery Mode or the debug log will name the file.
- 500, 502, or 504 errors typically point to PHP-FPM crashing or an upstream server timing out, not a WordPress-level bug at all.
- Database connection errors mean either the database server is unreachable, credentials in
wp-config.phphave changed, or (less commonly) a table got corrupted mid-write.
Before doing anything else, check for a WordPress-generated recovery email, since it names the exact plugin or theme at fault far faster than manual log-diving. Then head to Tools > Site Health if the dashboard loads at all. The loopback and cron checks there flag whether the server can talk to itself, a common casualty of WAF rules or misconfigured reverse proxies.
Run a couple of quick checks with curl to separate a front-end problem from an admin-side one:
curl -I https://yoursite.com
curl -I https://yoursite.com/wp-admin/
If the homepage returns 200 but /wp-admin/ returns 500, the problem is likely admin-specific, often a plugin that only loads in the dashboard. If both fail, you’re looking at a server-level or core-level issue.
Insufficient disk space is one of the more frequent, and most overlooked, causes of failed updates, particularly on shared hosting plans with tight quotas. It’s worth checking before you assume the fault lies with a specific plugin.
Finally, build a short timeline: what updated (core, plugin, or theme), was it manual or automatic, and did anything else update at the same time? Concurrent updates to a plugin and its required PHP extension, or a theme and its parent theme, are a common source of conflicts that look like one failure but are really two.
Which fixes are safe to try first?
Start with the changes you can undo in seconds, and work up to anything more invasive only if those don’t resolve it.
- Remove
.maintenanceonly once, and resist the urge to re-trigger the update immediately afterwards. One‑click updates usually complete without incident; re-running one on a site that’s already in an inconsistent state tends to make the inconsistency worse, not better. - Isolate the suspect plugin by renaming its folder via SFTP, not by deleting it. Renaming deactivates it while keeping its settings intact, so you can restore it once you’ve confirmed it isn’t the cause.
- If you have no strong suspect, rename the entire
pluginsfolder to something likeplugins-off, confirm the site loads, then rename it back and reactivate plugins one by one, testing after each. - Switch to a default theme (Twenty Twenty Four or similar) by renaming the active theme’s folder, or with WP-CLI:
wp theme activate twentytwentyfourThis rules out theme code as the cause in seconds.
- Only now, clear caches. Do it in this order: page cache plugin first, then server-level cache, then CDN cache last. Clearing them earlier can make a broken site look temporarily fine and hide whether your actual fix worked.
- If a plugin was mid-migration when it failed (common with database-migrating plugins during major version jumps), disable that plugin rather than restoring from backup immediately. Check the vendor’s documentation for a migration-recovery procedure first, since a blind restore can leave the database and codebase out of sync.
Pro Tip: Test after every single change, not after a batch of three. It’s the only way to know which action actually fixed things, which matters enormously when you’re writing up the incident for a client afterwards.
For deeper guidance on isolating theme-specific conflicts, including parent and child theme interactions, see WPCTO’s guide to safe theme updates.
How do you manually repair WordPress core files?
Manual core repair is a bigger step, and it’s only necessary when logs point specifically to wp-admin or wp-includes, or when the update screen itself reports a failed core update.
Back up whatever state exists first, even if it’s already broken. You want a reference point to compare against. Then confirm which WordPress version the database expects, visible in wp-includes/version.php or via WP-CLI, before you download anything.
- Download the exact matching WordPress
.zipfrom wordpress.org, matched to the version your database expects, not the newest available. - Extract it locally and inspect it before uploading anything.
- On the server, delete only the
wp-adminandwp-includesdirectories. Nothing else. - Upload the clean
wp-adminandwp-includesfolders from the extracted copy. - Upload the loose root files (
index.php,wp-load.php, and so on) but never overwritewp-config.php, and never touchwp-content. - Visit
/wp-admin/afterwards. If WordPress detects a pending database upgrade, let it run rather than second-guessing it.
This sequence, preserve evidence, replace core directories cleanly, then complete any pending database upgrade, is the standard safe recovery path, and it works because it never touches the two places your actual site lives: your content and your configuration.
If a database upgrade already ran partially before the failure, finish it once core files are consistent rather than rolling back randomly, since a partial migration followed by a mismatched core version is a worse state than either extreme on its own.
Where you have SSH access, WP-CLI makes this considerably safer:
wp core verify-checksums
wp core update --version=6.7.1
verify-checksums tells you exactly which core files differ from the official release, which turns guesswork into a precise list. Prefer SSH and WP-CLI over FTP wherever your hosting supports it; command-line operations are less prone to partial uploads and timeout-related corruption than dragging files over FTP.
Could the hosting environment itself be the problem?
Sometimes the WordPress installation is fine and the server underneath it isn’t. A few host-side issues consistently masquerade as WordPress bugs.
- Filesystem method conflicts. WordPress needs “direct” write access to update files without prompting for FTP credentials. If your logs show “Could not create directory” or the dashboard suddenly asks for FTP details it never asked for before, file ownership between PHP and the web server has likely drifted.
- Disk space and stale backups. Check available disk space before any major update, and clear
wp-content/upgrade-temp-backupif it’s accumulated old partial backups, a known cause of failed updates on constrained hosting plans. - PHP limits. “Allowed memory size exhausted” or “Maximum execution time exceeded” in your logs mean exactly what they say. A short-term fix is raising
memory_limitormax_execution_timeinphp.inior via your host’s panel, or simply running the update through WP-CLI, which isn’t bound by web server timeout limits the same way. - Stale OPcache. PHP’s OPcache can keep serving old bytecode after files have been correctly replaced, producing the confusing symptom of a site that looks half-updated, working on the front end but broken in the dashboard, or vice versa. Restart PHP-FPM through your host panel, or use a one-off
opcache_reset()script, to clear it. - Security plugins and WAF rules. If a firewall or security plugin blocks outbound requests to
api.wordpress.orgor the REST API, updates fail silently or repeatedly. Run the Site Health loopback test, and if it fails, pause security rules temporarily to confirm the theory before you go hunting elsewhere.
How do I confirm the site is properly fixed?
Getting the homepage to load again isn’t the finish line. Confirm the fix holds under real use before you call it done.
- Load
wp-adminand the front end separately, then click through a form submission, a login, and, on e-commerce sites, a test checkout. - Send a test email through the contact form or checkout flow to confirm mail delivery survived the incident.
- Re-run Site Health to check loopback requests and WP-Cron, since both are common casualties of the same server issues that caused the original failure.
- Watch the error log for 10 to 30 minutes of normal traffic before declaring victory. A fix that looks clean immediately after can still throw errors under load.
- Take a fresh backup now that the site is stable, and write down what happened: the trigger, the fix, and the root cause, for your own records and for the client.
- Schedule the next update deliberately, in staging, with a PHP compatibility check and a read of the plugin’s changelog, rather than letting auto-updates fire again unsupervised.
How can agencies prevent this from happening again?
Every recovery you do manually is a rehearsal for the workflow that would have prevented it. The gap between agencies who fight fires every month and agencies who don’t usually isn’t skill, it’s process.
- Staging that actually matches production. Same PHP version, same caching layer, same reverse proxy headers. A staging environment running PHP 8.1 while production runs 7.4 will pass tests that then fail live.
- Automated backups with tested restores. A backup you’ve never restored from is a hope, not a plan. Schedule quarterly test restores, not just nightly backups nobody’s checked in a year.
- Consistent file ownership. Half-finished updates often trace back to inconsistent PHP and web server user permissions during the write process. Standardising ownership removes a whole category of “direct filesystem method rejected” failures.
- A documented update window with pre-checks and monitoring. Update on a schedule, with a rollback plan already written down, not improvised at 11pm on a Tuesday.
For a fuller breakdown of what a staged rollout actually looks like in practice, WPCTO’s guide to WordPress staging for agencies is worth building your internal checklist around, alongside a broader workflow for regular updates.
There’s a business case buried in all this, too. Every hour your team spends firefighting a failed update is an hour not billed and not spent on the creative work your clients actually hired you for, so understanding UK website maintenance costs for SMEs can help frame your agency’s retainer pricing effectively. If you want to see what that firefighting is quietly costing you in unclaimed retainer revenue, run it through the WordPress Profit Calculator, it takes under 90 seconds and gives you a real number, not a guess.
Should you repair or optimise the database after a failed update?
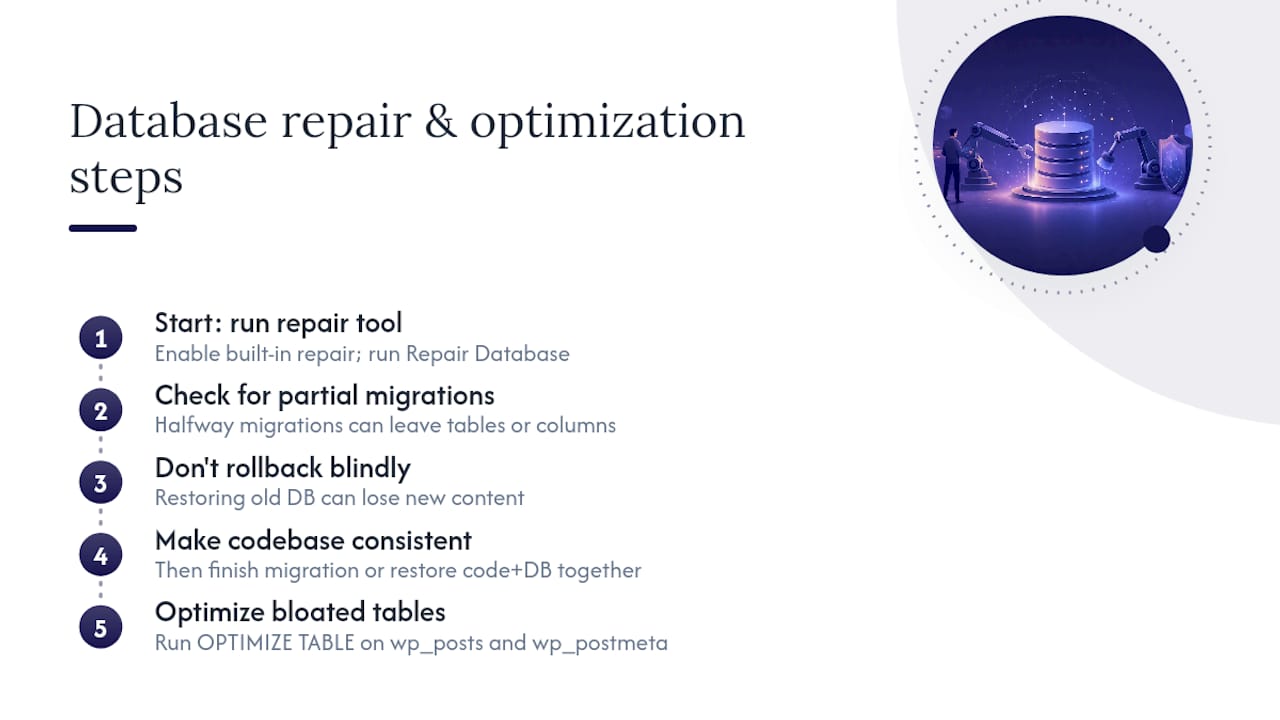
A failed update rarely corrupts a database outright, but it can leave it in a partially migrated or bloated state, and that’s worth checking before you assume the site is fully recovered.
Start with WordPress’s built-in repair tool. Add this line to wp-config.php temporarily:
define( 'WP_ALLOW_REPAIR', true );
Then visit yoursite.com/wp-admin/maintenance.php to run Repair Database, which checks and repairs corrupted tables using MySQL’s own repair routines. Remove the line from wp-config.php again once you’re done, since leaving it in place exposes the tool publicly.
If a plugin’s migration task failed partway through, don’t assume a rollback is the safe option. A migration that ran halfway can leave new tables or columns that a straight code rollback won’t remove, and restoring an old database over a partially migrated one risks losing content created after the update started. The safer route is to get the codebase into a consistent state first, then either let the migration complete on the current version or restore both code and database together from the same pre-update snapshot, never one without the other.
Once the site is stable, run OPTIMIZE TABLE on any tables that saw heavy writes during the failed migration, particularly wp_options and wp_postmeta, which tend to bloat fastest during interrupted plugin updates.
What do most agencies get wrong when an update fails?
The mistake I see most often isn’t technical, it’s behavioural. Someone panics and restores a backup without checking whether it’s the right backup, or restores just the database while leaving mismatched plugin files in place, and now there are two problems instead of one. The instinct to “just get it back” is understandable at 6pm on a Friday, but a calm, diagnostic-first pass consistently costs less downtime than a rushed one.
The second mistake is running production updates live, with no staging step, because “it’s just a minor version bump.” Minor version bumps are exactly the updates that get skipped in testing and cause the most surprise failures, because nobody expected them to matter.
None of this requires heroics. It requires a written playbook, applied the same way every time, and enough discipline to escalate rather than improvise when the first two fixes don’t work. Agencies that build that discipline in-house eventually realise it’s cheaper to hand the whole function to a partner who’s already built it, which turns unpredictable support hours into predictable retainer revenue instead.
— Marcel
Get WordPress update support that doesn’t land on your desk
A specialist partner can handle maintenance plans, plugin and theme management, hosting oversight, emergency recovery, and fractional CTO advice when a client needs deeper technical judgement, relieving your team from absorbing every plugin failure or urgent support call.
You keep the client relationship and the recurring revenue; we keep the update failures off your calendar. If you’re not sure how much that’s currently worth, run your numbers through the WordPress Profit Calculator, it shows the uncaptured revenue sitting in your existing client base in under 90 seconds. From there, take a look at Wpcto’s support services or book a discovery call to see whether a white-label arrangement fits how your agency already works.
Sources
- Upgrading WordPress — Developer Resources
- Common errors — Developer Resources
- An automated WordPress update has failed to complete: how to safely recover
- WordPress Core Update Failed? Safe Recovery Guide