

The fastest managed WordPress partner for a UK agency is not the one with the lowest TTFB on a benchmark page. It is the one that responds to a critical incident within one to four hours, restores a site from a tested backup within a documented RTO window, and deploys updates through a staging-first workflow with a clear rollback path. Those three operational measures are what protect your client relationships and your agency’s reputation.
Three criteria define “fastest” in this context:
- Critical-issue SLA: written commitment to initial response within one to four hours, with a named escalation contact
- Tested restore RTO/RPO: documented recovery time objective, with evidence of regular restore drills rather than untested backup files
- Deployment cadence: a staging-first workflow where every update is validated before it touches production
Raw server speed metrics such as TTFB and Core Web Vitals scores matter for client site performance, but they are infrastructure concerns. When you are evaluating an outsourced managed WordPress partner, operational speed is what you are actually buying.
Table of Contents
- How do the main partner archetypes compare for agencies?
- What does “fastest” actually mean? The metrics to measure
- How to vet a managed WordPress partner in 30 minutes
- What onboarding and SLAs should you expect from a partner?
- What Wpcto delivered for The Island: a real agency example
- How pricing models affect the speed you actually get
- Final decision checklist and a two-week pilot plan
- Key takeaways
- What I would do tomorrow if I were running a UK agency
- Wpcto: the agency-first managed WordPress partner for UK agencies
- Useful sources and documents to request during vetting
How do the main partner archetypes compare for agencies?
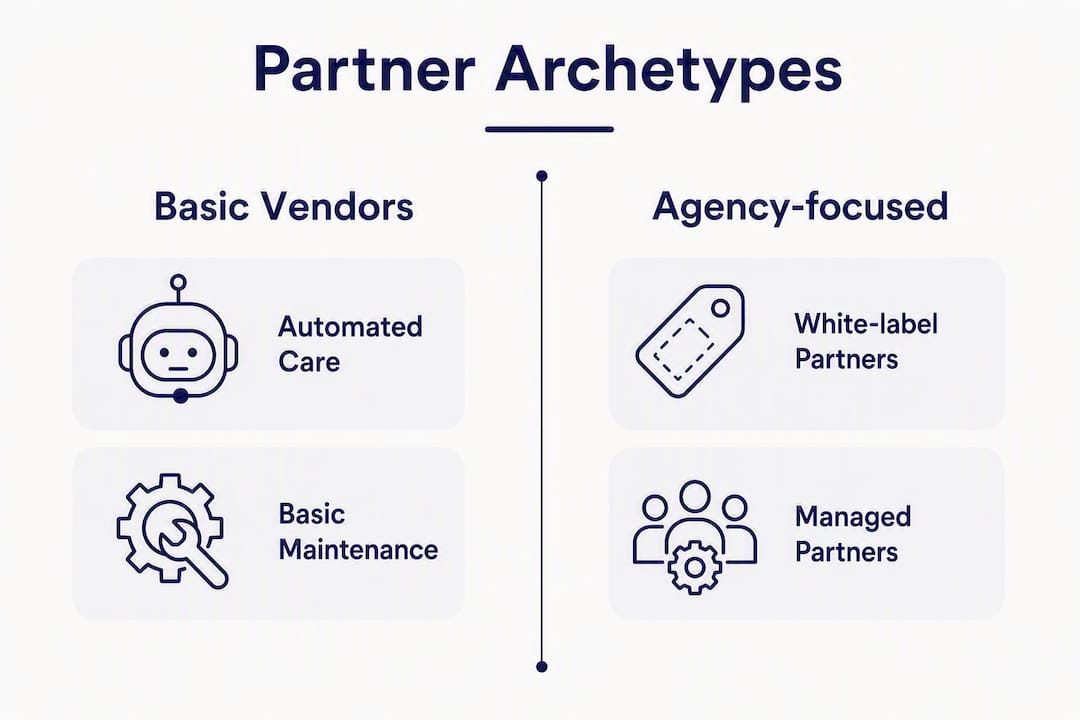
Agencies typically encounter four types of provider. Here is how they score on the dimensions that matter most.
| Dimension | Automated care tool | Basic maintenance vendor | Full white-label partner | Agency-first managed partner (e.g. Wpcto) |
|---|---|---|---|---|
| Critical-issue SLA | None | Best-effort, verbal | 1–4 hrs written | 1–4 hrs written |
| Standard-issue SLA | None | 24 hrs | 4–24 hrs written | 4–24 hrs written |
| Backup & tested restores | Scheduled only | Scheduled, rarely tested | Scheduled + periodic drills | Scheduled + documented restore drills |
| Staging-first workflow | No | Rarely | Yes | Yes, with rollback path |
| White-label reporting | No | No | Yes | Yes, agency-branded |
| Scope of services | Updates only | Updates + basic security | Full maintenance + security | Full maintenance, security, performance, migrations, emergency support |
| Onboarding speed | Immediate | 1–2 weeks | 2–4 weeks | Structured 30-day plan |
| UK support / data residency | No | Variable | Variable | Yes |
| Pricing shape | Per site, low cost | Per site or retainer | Tiered retainer | Tiered retainer or per-site |
| Escalation support | None | None | Named contact | Named contact + out-of-hours |
White-label fulfilment lets agencies keep the client relationship while a partner executes technical work under the agency’s own brand. For revenue-critical client sites, weight the critical-issue SLA and tested restore columns most heavily. A provider that scores well on white-label reporting but cannot commit to a written restore RTO is a liability, not a partner.
What does “fastest” actually mean? The metrics to measure
“Fastest managed WordPress hosting” in an agency outsourcing context means operational speed across four measurable dimensions.
- P1 initial response time: the clock from the moment a critical incident is reported to the first substantive reply. Industry guidance recommends one to four hours as a reasonable target; ask for this in writing.
- Resolution / restore RTO: how long it takes to restore a site to a working state. A credible partner documents a target RTO (commonly two to four hours for a full restore) and can show evidence of drills.
- RPO (Recovery Point Objective): the maximum age of the backup used in a restore. Daily backups with a 24-hour RPO are a minimum; revenue-critical sites warrant six-hourly or real-time snapshots.
- Deployment turnaround: time from a staged, validated update to production release. A staging-first workflow with a documented process typically achieves same-day or next-day deployment for routine updates.
- Performance fallbacks: TTFB under 200ms and Largest Contentful Paint under 2.5 seconds are reasonable targets for well-configured WordPress sites. These are outcomes of good infrastructure and caching, not SLA commitments.
- Uptime monitoring: continuous monitoring with alerting, not a weekly report. The partner should be aware of downtime before your client is.
Measure these using synthetic monitoring tools (such as UptimeRobot or Pingdom) alongside real user monitoring. Request incident postmortems after any P1 event so you can verify the partner’s actual response against their written SLA.
How to vet a managed WordPress partner in 30 minutes
Run this sequence with every candidate before you sign anything.
Interview questions to ask:
- Can you provide your SLA document in writing, with named incident tiers and response targets?
- How often do you run restore drills, and can you share a recent restore test report?
- Walk me through your staging workflow for a plugin update on a live client site.
- Who is my named escalation contact, and what happens if they are unavailable?
- Can I see a sample white-label report you would send under our agency brand?
Red flags to walk away from:
- Verbal-only SLA commitments with no written document
- No evidence of tested restores (“we have backups” is not the same as “we test them”)
- A single engineer handling all client sites with no documented handover procedure
- Reliance on a shared WordPress Multisite for multiple unrelated clients (a single point of failure that complicates individual client offboarding)
Two trial tasks to run before signing:
- Ask the candidate to perform a staged plugin update on a test site and roll it back. Time the process and check whether staging parity was maintained.
- Submit a simulated P1 ticket outside business hours. Record the time to first substantive response and compare it against their written SLA.
Pro Tip: Score each vendor answer as pass, partial, or fail against your written SLA requirements. Any “fail” on critical-issue response or tested restores is a disqualifier, regardless of price.
Vendor scorecards should include SLA model, security ownership, release quality and continuity evidence — not just a feature list.
What onboarding and SLAs should you expect from a partner?
A credible partner follows a structured onboarding timeline with named milestones.
Onboarding timeline:
- Week 1: Discovery, access matrix, credentials audit, baseline performance and security scan
- Week 1–2: Staging environment setup, staging parity validation, first restore drill
- Week 2–3: DNS cutover plan agreed, rollback path documented, client data handover confirmed
- Week 3–4: Production cutover, monitoring configured, first branded report issued
- Day 30: Stabilisation review, incident log reviewed, SLA performance confirmed
Migration checklist:
- Full offsite backup taken before any migration begins
- Staging environment matches production (PHP version, plugins, theme, database)
- Rollback path tested and documented
- Client data handling and GDPR responsibilities confirmed in writing
- Exit plan and data export procedure agreed before go-live
Example SLA table to request from any candidate:
| Incident tier | Initial response target | Resolution / RTO target | Notes |
|---|---|---|---|
| P1 (site down / security breach) | 1–4 hours | 2–4 hours | 24/7, named escalation contact |
| P2 (significant function broken) | 4–8 hours | Same business day | Business hours |
| P3 (standard request / update) | 4–24 hours | 2–5 business days | Business hours |
| Backup retention | Daily minimum | RPO: 24 hours | Tested restore monthly minimum |
On contract exit: confirm in writing that you receive all credentials, database exports, file archives and DNS records within a defined handover window. A partner that hesitates on exit terms is one worth reconsidering before you sign.
What Wpcto delivered for The Island: a real agency example
The Island is a design and digital agency that brought Wpcto in to manage hosting, maintenance and emergency support for their client portfolio. The objectives were clear: reduce incident response time, introduce a staging-first deployment workflow, and replace ad-hoc backups with tested restore drills.
Key technical interventions included a hosting migration to a more reliable infrastructure, a documented staging workflow for all plugin and theme updates, and a scheduled restore drill programme.
Outcomes from the engagement:
- Improved uptime consistency across the client portfolio
- Faster deployment cycles through the staging-first process
- Documented restore drills replacing untested scheduled backups
- White-label reporting delivered under The Island’s own brand
You can review the full case study and use it as a template for the evidence you request from any candidate during vetting.
How pricing models affect the speed you actually get
Not all pricing structures deliver the same response speed. The commercial model shapes the partner’s incentive to prioritise your incidents.
- Basic per-site maintenance plans (typically under £60/month): cover routine updates and monitoring. Emergency response is usually excluded or billed separately, often at rates of £500–£2,000 per incident for out-of-hours callouts.
- White-label tiered retainers (mid-range): include a defined scope of maintenance, security and reporting. Emergency response may be included up to a time cap; check whether P1 incidents are covered or billed additionally.
- Agency retainer with included emergency time: the model that most reliably delivers fast, guaranteed restores. The partner has a financial incentive to resolve incidents quickly because their time is already allocated.
- Per-incident emergency billing: fast in theory, but creates friction at the worst possible moment. You are negotiating cost while a client site is down.
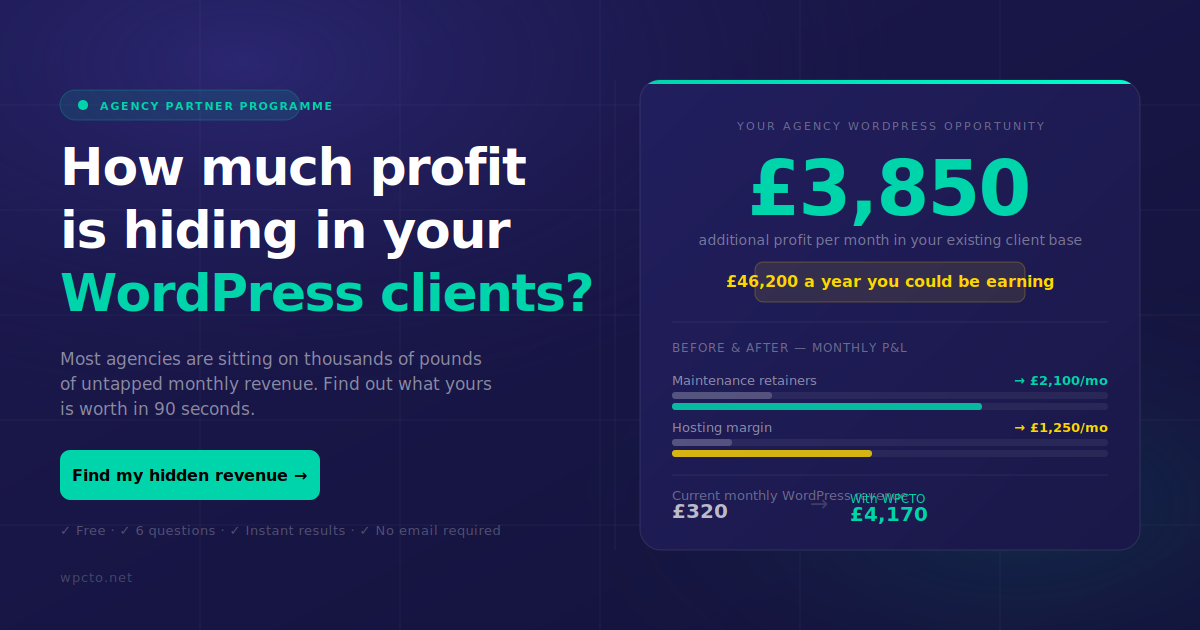
Before you commit to a pricing tier, model the actual margin impact. The WordPress Profit Calculator shows agencies exactly how much uncaptured recurring revenue sits in their existing client base and whether a higher monthly retainer is commercially justified.
Final decision checklist and a two-week pilot plan
Before you sign, confirm every item on this list.
- Written SLA document with named incident tiers, response targets and escalation contacts
- Evidence of tested restore drills (a restore test report, not just a backup schedule)
- Documented staging-first workflow with a rollback procedure
- White-label reporting template reviewed and approved
- Named point of contact and a documented cover procedure when they are unavailable
- Exit terms confirmed in writing: credentials, data export, DNS handover timeline
Two-week pilot plan:
- Days 1–3: Onboard one non-critical client site. Confirm staging environment parity.
- Days 4–7: Submit the staged update trial task. Record time and process quality.
- Days 8–10: Submit the simulated P1 ticket. Record response time against written SLA.
- Days 11–14: Review monitoring data, request the first branded report, confirm restore drill evidence.
- Acceptance criteria: P1 response within the written SLA window, staging workflow completed without production impact, restore drill evidence provided.
Run the WordPress Profit Calculator before the pilot begins. It takes under 90 seconds and gives you a clear picture of the recurring revenue you can capture by outsourcing maintenance at the right price point.
Key takeaways
The fastest managed WordPress partner for a UK agency is the one with written SLAs, tested restore drills, and a staging-first workflow — not the one with the lowest server benchmark.
| Point | Details |
|---|---|
| Three speed metrics to insist on | Written P1 response SLA (1–4 hrs), documented restore RTO, and staging-first deployment with rollback. |
| Tested restores beat scheduled backups | Ask for a restore drill report; a backup schedule alone is not evidence of recovery capability. |
| Pricing model shapes response speed | A retainer with included emergency time delivers faster, more reliable incident response than per-incident billing. |
| Pilot before you commit | Run a two-week pilot with the staged update task and a simulated P1 ticket before signing a long-term contract. |
| Wpcto for UK agencies | Wpcto provides written SLAs, staging-first workflows, tested restore drills and white-label reporting for UK design and brand agencies. |
What I would do tomorrow if I were running a UK agency
The mistake most agency owners make is treating managed WordPress support as a commodity purchase decided on price. The real question is: what does a client site going down at 11pm on a Friday cost you? Not just in emergency hours, but in the client relationship, the retainer renewal, the referral you do not get.
Outsourcing to a speed-focused partner protects your senior people from routine maintenance and frees them for the work that actually grows the agency. The commercial case is straightforward once you model it properly. Before you shortlist a single provider, spend 90 seconds on the WordPress Profit Calculator to see the recurring revenue your existing client base could generate under a properly priced maintenance model. Then vet partners against the checklist above, run the two-week pilot, and sign only when the SLA is in writing.
Wpcto: the agency-first managed WordPress partner for UK agencies
Agencies that have been absorbing WordPress support costs quietly for years often find the same thing when they model it properly: the margin was always there. Wpcto is built to capture it for you.
Wpcto handles staging-first deployments, tested restore drills, security monitoring, performance optimisation, hosting management and emergency support, all under your agency’s brand. Your clients see your name on every report. You keep the relationship and the recurring revenue. We handle every WordPress ticket.
The agency services partnership is designed for UK design, brand and digital agencies of 2–50 people who want to stop absorbing WordPress costs and start charging for them properly. Run the WordPress Profit Calculator to see what your client base is worth, then get in touch to arrange a two-week pilot.
Useful sources and documents to request during vetting
Wpcto resources:
- Agency services partnership: the primary starting point for agencies considering a Wpcto partnership
- White-label WordPress support: how Wpcto operates invisibly under your agency brand
- The Island case study: real outcomes from an agency engagement, including staging workflow and restore drill evidence
- WordPress Profit Calculator: model your uncaptured recurring revenue in under 90 seconds
- Hosting and migration services: details on migration, rehosting and staging setup
Documents to request from any candidate during vetting:
- SLA document (PDF): incident tiers, response targets, escalation contacts
- Security runbook: patch governance, vulnerability response process, WAF and monitoring configuration
- Restore drill report: evidence of a recent tested restore with RTO recorded
- Staging workflow checklist: the step-by-step process from update to production release
Contact Wpcto directly to request template versions of these documents or to arrange a two-week pilot.