

The right approach combines external uptime checks, real-user performance data (Web Vitals) and internal server metrics into one picture, not three separate dashboards nobody reads. Add profiling tools to find root causes, severity-based alerts that route straight into tickets, and runbooks so anyone on the rota knows what to do. Treat every check as code, version it, and test it like you would test a feature.
TL;DR:
- External and internal monitoring should be combined to quickly identify whether outages are caused by code, network issues, or hosting problems.
- Tracking key Web Vitals percentiles like p95 and p99 provides better insights into user experience than averages alone, especially during load spikes.
- Using checks as code, with thresholds and TTLs stored in version control, enables better testing and reliability of monitoring systems.
- Implementing severity levels and integrating alerts with ticketing reduces alert fatigue and ensures immediate, appropriate responses to critical incidents.
- Agencies should prioritize simple, actionable checks, write clear runbooks, and consider outsourcing monitoring management to save time and deliver measurable client value.
Table of Contents
- Best practices for WordPress monitoring: what to actually watch
- Internal versus external monitoring: why you need both
- Which performance KPIs matter, and how to read percentiles
- Best WordPress monitoring plugins and profiling tools compared
- Designing alerts that don’t cause fatigue
- Writing checks as code: thresholds, TTLs and drills
- Choosing WordPress monitoring plugins and tools by category
- Operationalising monitoring inside an agency’s delivery model
- What most agencies get wrong about monitoring
- Let WPCTO run your monitoring, so your team doesn’t have to
- Sources
Best practices for WordPress monitoring: what to actually watch
Most agencies monitor too little in the wrong places and too much in places that don’t matter. A sensible baseline covers four categories, and skipping any one of them leaves a blind spot that eventually turns into a Sunday evening phone call.
Start with synthetic checks on the homepage plus one or two business-critical routes, such as login, checkout, or the site search. These simulate a real visitor and catch failures your hosting dashboard will never flag. Layer in error tracking next: 4xx and 5xx response codes, PHP fatal errors, and anything showing up repeatedly in application logs. A spike in 500 errors after a plugin update is one of the most common incidents agencies miss until a client reports it.
Server-side metrics matter just as much. CPU load, memory consumption, disk space, database connection counts, and slow-query logs tell you when a site is heading towards trouble before visitors notice anything.
Finally, track frontend performance directly:
- Time to First Byte (TTFB), which flags server or hosting bottlenecks
- Largest Contentful Paint (LCP) and Cumulative Layout Shift (CLS)
- Interaction to Next Paint (INP) or Time to Interactive (TTI)
- Slow transactions, meaning any request that takes noticeably longer than the median
The WordPress Advanced Administration Handbook makes the point plainly: uptime for users means more than services simply responding, which is why performance data has to sit alongside availability checks, not replace them.
Internal versus external monitoring: why you need both
Internal monitoring watches your infrastructure from the inside. It reads CPU load, memory, disk I/O, and application logs directly off the server, which makes it excellent for diagnosing why something is slow. External monitoring does the opposite: it emulates a visitor, hits your site from outside your network, and tells you whether the thing is actually reachable, regardless of what your internal dashboards say.
The distinction matters because internal metrics can look perfectly healthy while the site is down for everyone else, a firewall rule, a DNS problem, or a CDN outage will never show up in server logs. A hybrid setup solves this:
- Internal metrics from something like Prometheus or host level agents, feeding dashboards your team checks daily
- External synthetic checks running from multiple geographic locations, independent of your own infrastructure
- Cross referencing both when an alert fires, so you know within minutes whether it’s a code problem or a network problem
For agencies juggling dozens of client stacks on different hosts, this hybrid model is the only way to get a consistent view. Hosting providers who separate their internal monitoring from independent external checks tend to catch outages faster precisely because they’re not relying on a single vantage point.
Which performance KPIs matter, and how to read percentiles
Field data (Real User Monitoring) captures what actual visitors experience; lab data from synthetic tests catches regressions before they reach production. You need both. The WordPress performance handbook recommends gathering field performance data precisely because synthetic tests, run from a single location under controlled conditions, routinely miss what happens on a patchy mobile connection in a different country.
Your KPI set doesn’t need to be long, but it does need to be the right five:
Core KPI set: LCP, CLS, INP (or FID on older setups), TTFB, and transaction response time at the 95th and 99th percentiles, alongside your overall error rate.
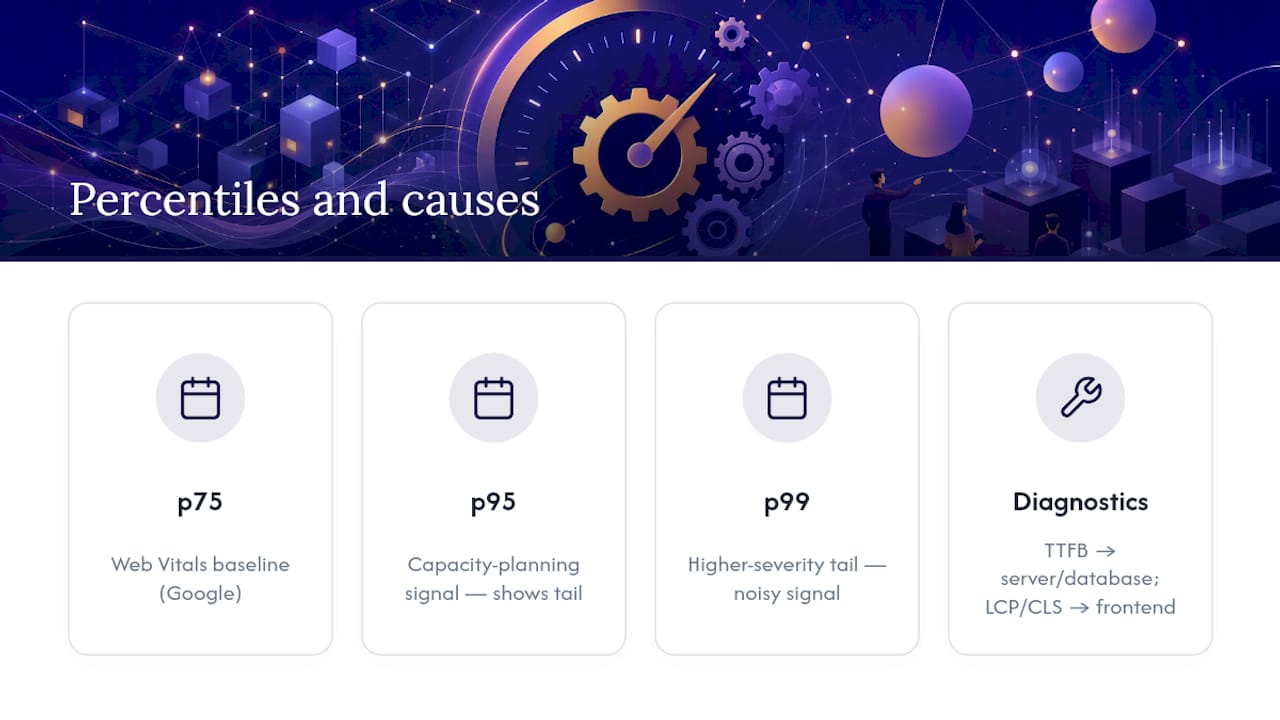
Averages lie. If your average page load is 1.8 seconds but your p95 is 6 seconds, one in twenty visitors is having a genuinely bad experience, and averages will never show you that. Percentiles matter because they surface the tail: the slow database query that only triggers under load, the third-party script that occasionally times out, the checkout page that crawls for users on a specific hosting node.
Use p75 as your baseline threshold for Web Vitals, since that’s the benchmark Google’s own scoring uses, and treat p95/p99 as your capacity planning signal, not your alerting trigger, since they’re naturally noisier. When TTFB creeps up specifically, look at your server and database first. When LCP or CLS degrade while TTFB stays flat, the problem is almost always frontend, images, layout shifts, or a heavy script blocking render.
Best WordPress monitoring plugins and profiling tools compared
Profiling is a workflow, not a single tool, and knowing which one to reach for at each stage saves hours of guesswork.
Start with Query Monitor during development or a live debugging session. It shows every database query for the current page load and its “Queries by Component” view attributes slow query time directly to a specific plugin or theme, which is usually the fastest way to find a culprit without touching a profiler.
When you need to compare performance across code changes, move to XHProf and XHGui. XHProf captures function call counts, execution duration and memory consumption for a request, and XHGui gives you a browsable interface to compare runs by wall time and memory, which makes it the right tool when you’re validating whether a deploy actually fixed something.
For production tracing across a live site, that’s where APMs earn their cost. New Relic, AppDynamics and Tideways trace slow functions, external HTTP calls and slow database queries in real time, and most support multi-location synthetic monitoring alongside application tracing.
- Quick attribution in a live incident: Query Monitor
- Comparative profiling across code changes: XHProf / XHGui
- Continuous production tracing and multi-location synthetics: New Relic, AppDynamics, Tideways
Pro Tip: Run Query Monitor first, always. If it points clearly at one plugin, you rarely need to open a profiler at all. Save XHProf and APM tracing for problems Query Monitor can’t explain.
The workflow that ties this together: alert fires, quick attribution with Query Monitor, targeted profiling if the cause isn’t obvious, a fix, then a regression check against the same KPIs that flagged the problem. Skip the last step and you’ll be back here in a fortnight. Our developer’s guide to performance troubleshooting walks through this profiling sequence in more depth.
Designing alerts that don’t cause fatigue
Alert fatigue kills monitoring programmes faster than any technical failure. If every alert pages someone at 2am, people start ignoring alerts, and the one that actually matters gets missed. Building alerts properly means designing severity into the system from day one.
- Define three severity levels, page, critical and warning, and map each to a specific response SLA (page means someone acts within minutes; warning can wait until morning).
- Use multi-location failure rules for synthetic checks. New Relic’s approach requires multiple locations to fail, with a 24 hour evaluation buffer, before it pages anyone, which filters out single-location blips that aren’t real outages.
- Write concise alert messages that include ownership, a runbook link, and the actual next step, not just “site down.”
- Integrate every alert with your ticketing system so nothing depends on someone remembering to log it, and maintain an on-call rota with clear escalation, similar to how PagerDuty structures its rotations.
The GOV.UK developer documentation on Prometheus, Grafana and Alertmanager is blunt about this: avoid informational or debug-only alerts entirely, because every low-value alert erodes trust in the ones that genuinely need a response. Reserve out-of-hours pages for true page-severity incidents, not anything that can reasonably wait until the working day starts.
Writing checks as code: thresholds, TTLs and drills
Monitoring checks should live in your codebase, not in someone’s head or a wiki page nobody updates. Gov recommends writing monitoring checks alongside application code and treating them as tests, which means they get version control, a review process, and basic CI validation before they go live.
Practical steps that make this work day to day:
- Store checks in the same repository as the site, with a clear commit history when thresholds change
- Set evaluation windows or TTLs on synthetic checks, typically 24 hours for location-based failures, to stop a single flaky probe from paging anyone
- Run periodic PagerDuty-style escalation drills to confirm the routing actually works, not just that the check fires
- Add canary checks that deliberately trigger a known alert path, confirming the whole chain from detection to notification functions
- Document each check’s intent and its expected normal range directly in the runbook, so whoever’s on call isn’t guessing whether a number is actually a problem
Our guide to automated WordPress testing covers how to wire these checks into a CI pipeline if you’re starting from scratch.
Choosing WordPress monitoring plugins and tools by category
Picking a stack starts with knowing which category solves which problem, because no single tool does everything well.
- External synthetics, services like UptimeRobot, check availability and response time from outside your infrastructure, often from multiple regions
- RUM collectors gather real visitor performance data (Web Vitals) directly from browsers in production
- APMs such as New Relic, AppDynamics and Tideways provide deep tracing across requests, database calls and external HTTP requests
- Log aggregation tools centralise error and access logs across every site you manage
- Dashboards, commonly Grafana paired with Prometheus for metrics storage, visualise everything in one place
- Alert routing, Alertmanager sitting alongside Prometheus and Grafana, handles severity based notification
- Uptime plugins built for WordPress specifically, useful for smaller sites that don’t need a full external stack
Before committing to any combination, run through a short checklist: does it support multi-location checks, how long does it retain data and can you export it, does it integrate with your ticketing system, and what does the pricing actually look like at the number of sites you manage today, and in twelve months.
A WordPress plugin is often genuinely enough for a single site with modest traffic. The moment you’re managing multiple client sites, need multi-location synthetics, or want proper APM-level tracing under real load, you need external services sitting above the plugin layer, not instead of it.
Operationalising monitoring inside an agency’s delivery model
Monitoring only earns its cost when it’s tied to something the client actually sees. Feed your KPIs, uptime percentage, error rate, response time, straight into monthly client reports, and suddenly monitoring stops looking like overhead and starts looking like proof of value.
Build this into delivery properly:
- Map monitoring metrics directly to whatever SLA you’ve agreed with the client, so a breach is measurable, not a judgement call
- Write runbooks for the incidents that recur most, hacked site, failed update, database exhaustion, with named owner contacts on each one
- Package monitoring inside your care plans as a distinct line item, and offer white-label reporting if you’re delivering it through a partner
- Decide honestly between in-house monitoring and a managed partner based on volume: below a handful of sites, in-house is manageable; beyond that, the on-call burden usually outweighs the margin
Our uptime monitoring guide for digital agencies breaks down how to price this as a recurring line rather than an absorbed cost.
What most agencies get wrong about monitoring
Three quick wins fix most of what’s broken in a typical agency’s setup within a week. First, add multi-location synthetic checks on your top five client sites, that alone eliminates most false-positive pages. Second, write down severity levels and actual response times for each one, even a rough version beats none. Third, put one runbook in place for your most common incident, usually a failed update or a hacked site.
The most common mistake isn’t a missing tool. It’s treating monitoring as a dashboard to glance at rather than a system with defined ownership and response times. Agencies that skip severity design end up either ignoring everything or panicking over nothing.
Present monitoring to clients as a measurable line item, uptime percentage, incident response time, monthly report, rather than a vague “we keep an eye on it.” Clients pay for things they can see the value of, and a monitoring report is one of the easiest value stories in WordPress support to tell.
— Marcel
Let WPCTO run your monitoring, so your team doesn’t have to
Consider outsourcing monitoring stack management instead of building an in-house system from scratch. This alternative involves handing over SLA-backed monitoring, incident response, and white-label reporting your clients never know isn’t yours, to a team experienced in serving agencies.
That includes security monitoring for core, themes and plugins, enhanced security updates when vulnerabilities surface, and emergency response when something breaks outside office hours. If you’re wondering whether this is worth the switch, the fastest way to find out is the WordPress Profit Calculator, it shows in under 90 seconds how much recurring revenue is sitting untapped in your existing client base. Run your numbers, then get in touch about our agency services or white-label support to arrange a pilot on a handful of sites before rolling it out across your whole portfolio.
Sources
- Monitoring – Advanced Administration Handbook
- Gov
- Measuring performance – Core Performance – WordPress.org
- Prometheus, grafana and alertmanager – GOV.UK Developer Documentation